# Multimodal Structured Decisions in Java with Gemini Decision 1 and the Interactions SDK
Back in September, I wrote about [Multimodal Decision Models: From DiffusionGemma and Jev to LangChain4j]({{< ref "/posts/2026/09/24/multimodal-decision-models-with-diffusiongemma-jev-and-langchain4j.md" >}}). In that experiment, I deployed Matt Mastracci's `djev` and `DiffusionGemma` on a Cloud Run Blackwell GPU and re-enabled the SigLIP vision encoder so I could classify cat pictures in a single forward pass.
This week, Google DeepMind launched **[Gemini Decision 1](https://ai.google.dev/gemini-api/docs/models/gemini-decision-1)** (`gemini-decision-1`) and the **[Gemini Decisions API](https://ai.google.dev/gemini-api/docs/decisions-api)** (`POST /v1beta/decisions`). Instead of self-hosting a 26B diffusion checkpoint on dedicated GPU instances, you can now get managed, calibrated "System 1" decisions directly through a Gemini API endpoint.
To bring this capability to Java right away, I implemented full Decisions API support and released **[version 2.2.0 of my Gemini Interactions API Java SDK](https://github.com/glaforge/gemini-interactions-api-sdk/releases/tag/v2.2.0)** on Maven Central. I also rebuilt my **Purrfect Match** cat classifier demo as a CPU-only Cloud Run service powered by `gemini-decision-1`, alongside the original GPU edition.
> [!NOTE]
> **Links & coordinates at a glance:**
> - Live demo powered by `gemini-decision-1` (CPU-only Cloud Run): [purrfect-match.cloud.run](https://purrfect-match.cloud.run)
> - Self-hosted `DiffusionGemma` GPU edition for comparison: [purrfect-match-gpu.cloud.run](https://purrfect-match-gpu.cloud.run)
> - [Gemini Interactions API Java SDK on GitHub](https://github.com/glaforge/gemini-interactions-api-sdk) and [v2.2.0 release notes](https://github.com/glaforge/gemini-interactions-api-sdk/releases/tag/v2.2.0)
> - Maven Central (`2.2.0`): [`io.github.glaforge:gemini-interactions-api-sdk:2.2.0`](https://central.sonatype.com/artifact/io.github.glaforge/gemini-interactions-api-sdk)
> - Official documentation: [Gemini Decisions API guide](https://ai.google.dev/gemini-api/docs/decisions-api) and [Gemini Decision 1 model page](https://ai.google.dev/gemini-api/docs/models/gemini-decision-1)
## System 1 Decisions with Zero Output Tokens (and Why Multimodality Matters)
Standard generative interactions (`POST /v1beta/interactions`) generate output autoregressively, one token at a time. When all your application needs is routing, content moderation, rubric grading, or structured classification, asking a chat model to emit formatted JSON adds decoding latency and output token cost.
The Decisions API takes the opposite approach. You pass one shared context and a map of up to **1,000 independent questions**, and `gemini-decision-1` scores every question in a single prefill forward pass:
- **Input budget:** up to **262,144 input tokens** for the shared context, with up to **16,384 tokens** per individual question.
- **Zero output tokens:** `usage().totalOutputTokens()` is always `0`. Pricing is billed at **\$0.10 per 1M input tokens**, with zero output token charges.
- **Latency:** typical text evaluations finish in roughly **150 to 250 ms**, while full image uploads over HTTPS roundtrip in around **400 ms**.
Like the Jev architecture I explored earlier, `gemini-decision-1` exposes three typed question primitives:
1. **`noul` (Yes/No):** evaluates a binary statement and returns a calibrated probability between `0.01` and `0.99`, plus a confidence score.
2. **`choice` (Single-select):** evaluates `2` to `255` mutually exclusive options and returns the winning key, softmax probabilities across every option, and confidence.
3. **`score` (Rubric rating):** evaluates `2` to `255` ordered rubric levels (indexed starting at `0`) and returns a probability-weighted continuous expected score, the level legend, per-level probabilities, and confidence.
Most teams first think of classification and routing as text-only workloads: triaging support tickets, checking policy compliance, or selecting agent tools. Just like `DiffusionGemma`, **`gemini-decision-1` is natively multimodal**. It accepts text, images, audio, video, and PDFs as shared input.
That multimodal foundation is why analyzing cat and non-cat photos is such a good stress test. Instead of forcing a vision-language model to generate prose or JSON, you send image bytes once, ask three different kinds of visual questions (`noul`, `choice`, and `score`) in parallel, and get calibrated probability distributions back.
## Adding the Gemini Interactions Java SDK v2.2.0
To use `gemini-decision-1` from Java 21+, add `io.github.glaforge:gemini-interactions-api-sdk:2.2.0` to your build configuration.
In Maven (`pom.xml`):
```xml
io.github.glaforgegemini-interactions-api-sdk2.2.0
```
In Gradle (`build.gradle.kts`):
```kotlin
implementation("io.github.glaforge:gemini-interactions-api-sdk:2.2.0")
```
The SDK models the Decisions API with a sealed `Question` hierarchy, a sealed `Answer` hierarchy, and a fluent `DecisionParams` builder:
```text
DecisionParams (model = "gemini-decision-1", shared input, questions)
├── Question.NoulQuestion ──► Answer.NoulAnswer (noul, yesProbability, confidence)
├── Question.ChoiceQuestion ──► Answer.ChoiceAnswer (choice, probabilities, confidence)
└── Question.ScoreQuestion ──► Answer.ScoreAnswer (score, legend, probabilities, confidence)
```
## Driving `gemini-decision-1` from Java
You call the Decisions API using the exact same `GeminiInteractionsClient` you use for regular interactions, via `client.createDecision(params)`. Let's look at a quick text routing example first, then the multimodal image classifier powering Purrfect Match.
### Text Routing and Triage in One Call
When building `DecisionParams`, `.model(...)` defaults to `ModelOption.GEMINI_DECISION_1` (`"gemini-decision-1"`). You can mix `.noul(...)`, `.choice(...)`, and `.score(...)` questions in one request:
```java
import io.github.glaforge.gemini.interactions.GeminiInteractionsClient;
import io.github.glaforge.gemini.interactions.model.Answer;
import io.github.glaforge.gemini.interactions.model.Decision;
import io.github.glaforge.gemini.interactions.model.DecisionParams;
import java.util.Map;
GeminiInteractionsClient client = GeminiInteractionsClient.builder()
.apiKey(System.getenv("GEMINI_API_KEY"))
.build();
DecisionParams params = DecisionParams.builder()
.input("The blue ceramic mug I ordered arrived shattered in pieces, and I was charged twice.")
.noul("is_damaged", "Did the item arrive physically damaged?")
.choice("department", "Which department should handle the duplicate charge?", Map.of(
"billing", "Payments, invoices, duplicate charges, and refunds.",
"technical", "Software or technical product usage issues.",
"other", "Anything outside these categories."
))
.score(
"severity",
"How severe is the physical condition of the delivered mug?",
"Intact: no visible damage.",
"Minor blemish: small scratch, still usable.",
"Destroyed: broken or shattered, completely unusable."
)
.build();
Decision decision = client.createDecision(params);
Answer.NoulAnswer damaged = decision.noulAnswer("is_damaged");
Answer.ChoiceAnswer department = decision.choiceAnswer("department");
Answer.ScoreAnswer severity = decision.scoreAnswer("severity");
System.out.printf("Damaged prob: %.2f | Department: %s | Severity: %.2f (%s)%n",
damaged.yesProbability(),
department.choice(),
severity.score(),
severity.topLevelDescription()
);
System.out.println("Output tokens billed: " + decision.usage().totalOutputTokens());
```
A few practical details to notice here:
- Each `noulAnswer(...)` exposes `noul()` (the raw probability from `0.01` to `0.99`), `yesProbability()`, `noProbability()`, and `confidence()`.
- Each `scoreAnswer(...)` evaluates levels indexed from `"0"` to `N - 1`. You can inspect the continuous weighted `score()`, call `topLevelKey()` / `topLevelDescription()` for the winning rubric level, or call `normalizedScore()` to map any rubric scale onto `[0.0, 1.0]`.
- `decision.usage().totalOutputTokens()` is strictly `0`.
### Multimodal Visual Decisions: Cat or Imposter?
Because `DecisionParams.Builder.input(...)` accepts `Content...` blocks (`TextContent`, `ImageContent`, `AudioContent`, `VideoContent`, and PDF `DocumentContent`), evaluating images works with the exact same builder pattern. Here is how **Purrfect Match** calls `gemini-decision-1` from `GeminiDecisionCatClassifierService`:
```java
import io.github.glaforge.gemini.interactions.model.Answer;
import io.github.glaforge.gemini.interactions.model.Content.ImageContent;
import io.github.glaforge.gemini.interactions.model.Decision;
import io.github.glaforge.gemini.interactions.model.DecisionParams;
import io.github.glaforge.gemini.interactions.model.ModelOption;
import java.util.List;
import java.util.Map;
Map furTypeCriteria = Map.of(
"calico", "Calico or tortoiseshell coat with patches of orange/red, black/brown, and white",
"tabby", "Tabby patterned coat with distinct stripes, swirls, or spots",
"ginger", "Ginger, orange, marmalade, or red coat",
"black", "Solid black or predominantly black dark coat",
"white", "Solid white or predominantly white coat",
"bicolor", "Bicolor, tuxedo, or piebald coat with two contrasting colors",
"colorpoint", "Colorpoint pattern with darker face, ears, paws, and tail like a Siamese"
);
DecisionParams params = DecisionParams.builder()
.model(ModelOption.GEMINI_DECISION_1)
.input(new ImageContent(imageBytes, mimeType))
.noul(
"is_cat",
"Is the primary subject depicted in this picture a domestic cat or kitten?",
"The image clearly shows a domestic cat or kitten.",
"The image shows another animal (such as a dog), an object, a person, or no cat."
)
.choice(
"fur_type",
"What is the primary coat color or fur pattern of this cat?",
furTypeCriteria
)
.score(
"fluffiness",
"How fluffy and voluminous is the cat's fur coat?",
List.of(
"Sleek, short coat close to the body",
"Medium coat with soft texture and moderate tufts",
"Extremely long, dense, voluminous, fluffy coat like a Persian or Maine Coon"
)
)
.build();
Decision decision = client.createDecision(params);
if (decision.isBlocked()) {
throw new IllegalArgumentException(
"Blocked by safety filter: " + decision.promptFeedback().blockReason()
);
}
Answer.NoulAnswer isCatAns = decision.noulAnswer("is_cat");
Answer.ChoiceAnswer furAns = decision.choiceAnswer("fur_type");
Answer.ScoreAnswer fluffAns = decision.scoreAnswer("fluffiness");
boolean isCat = isCatAns.noul() >= 0.5;
String winningFur = furAns.choice();
double fluffScore = fluffAns.score();
```
If you want to reduce image token consumption when high resolution detail is not needed, `ImageContent` in v2.2.0 also accepts a resolution hint (`new ImageContent(imageBytes, mimeType, Content.Resolution.LOW)`). And when `decision.isBlocked()` is true, `decision.promptFeedback().blockReason()` tells you why input content filters rejected the payload (`SAFETY`, `IMAGE_SAFETY`, `PROHIBITED_CONTENT`, and so on).
> [!TIP]
> If you build custom proxies, webhooks, or mock servers using the `gemini-interactions-server` module, `InteractionsHandler` also supports `createDecision(DecisionParams)` to route `POST .../decisions` requests on the server side.
## Purrfect Match on Cloud Run: Managed Gemini Decision 1 vs. Self-Hosted GPU
To compare the new managed model directly against my September setup, I refactored the Micronaut 5 / Java 25 application into a multi-module Gradle build. A shared module (`cat-classifier-common`) holds the web UI, security headers, IP rate limiting, and classification rubrics, while two separate Cloud Run services implement the backend:
- **[purrfect-match.cloud.run](https://purrfect-match.cloud.run):** runs `cat-classifier-decision-one` on standard CPU-only Cloud Run, authenticating to `gemini-decision-1` with an API key stored in Secret Manager.
- **[purrfect-match-gpu.cloud.run](https://purrfect-match-gpu.cloud.run):** runs `cat-classifier-gpu`, forwarding requests to the self-hosted `DiffusionGemma` + `djev` + `vLLM` container running on an NVIDIA RTX PRO 6000 Blackwell GPU.
Testing the **Calico Beauty** preset in the live `gemini-decision-1` edition shows all three questions evaluated simultaneously in **480 ms** end-to-end:
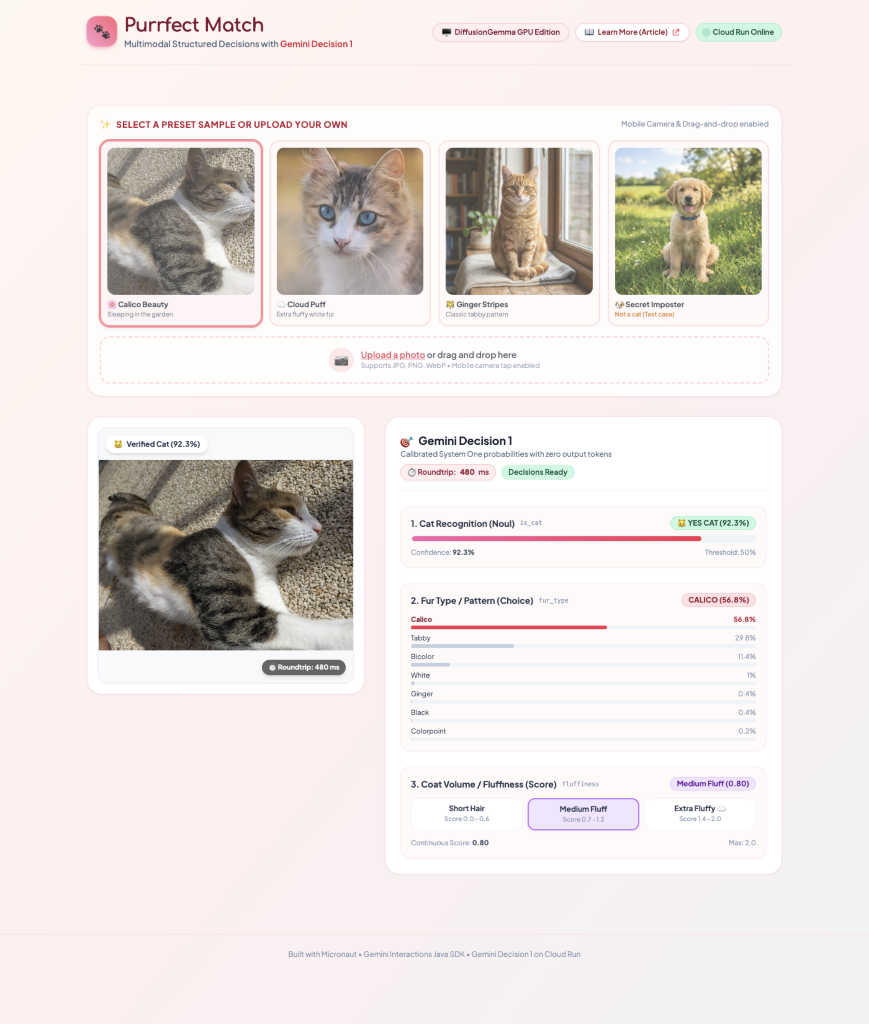
`gemini-decision-1` classifies the photo as a verified cat (`92.3%`), picks `Calico` (`56.8%`, with `Tabby` at `29.8%` and `Bicolor` at `11.4%`, capturing the patched calico-tabby coat nicely), and scores fluffiness at `0.80` (`Medium Fluff`).
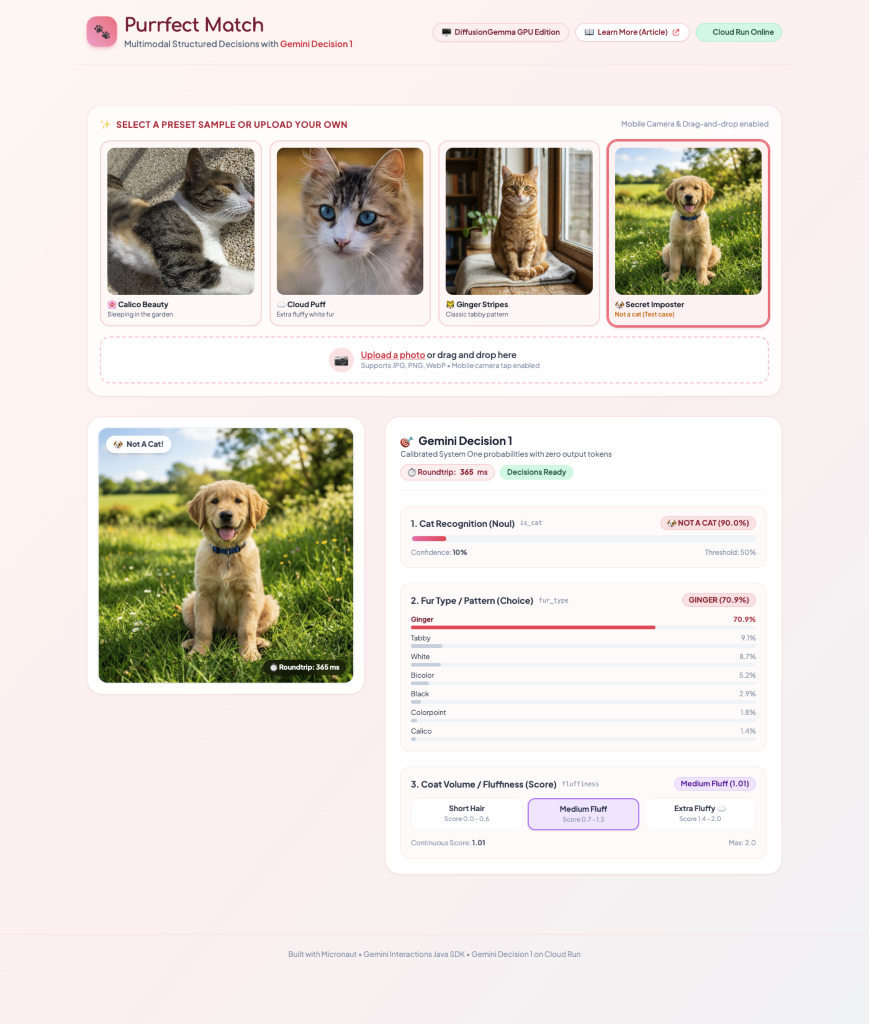
Clicking the **Secret Imposter** sample swaps in a Golden Retriever puppy photo. In **365 ms**, `is_cat` drops to `10%` (`90.0% NOT A CAT`), flipping the verdict banner cleanly while still computing coat color (`Ginger`, `70.9%`) and fluffiness (`1.01`) in the same pass:
Having both versions running side-by-side on Cloud Run makes the operational trade-offs very concrete:
| Dimension | Managed `gemini-decision-1` | Self-Hosted `DiffusionGemma` + `djev` |
| :--- | :--- | :--- |
| **Live demo** | [purrfect-match.cloud.run](https://purrfect-match.cloud.run) | [purrfect-match-gpu.cloud.run](https://purrfect-match-gpu.cloud.run) |
| **API endpoint** | `POST /v1beta/decisions` | `POST /v1/systemone` (vLLM + middleware) |
| **Cloud Run hardware** | CPU-only Micronaut container | Micronaut frontend + 20 vCPU, 80 GiB RAM, 1× RTX PRO 6000 GPU |
| **Scale-to-zero cold start** | ~1 to 2 seconds (JVM startup) | ~90 seconds (loading 26B weights onto GPU) |
| **Warm request latency** | ~350 to 500 ms over HTTPS | ~130 to 200 ms once the GPU container is warm |
| **Supported inputs** | Text, Images, Audio, Video, PDFs (up to 256K tokens) | Text and Images (SigLIP vision encoder) |
| **Best fit** | Zero ops, instant scale-to-zero, broad multimodal inputs | Open weights, private VPC hosting, high sustained GPU throughput |
For bursty traffic or scale-to-zero Cloud Run apps, eliminating that ~90-second GPU weight-loading cold start makes a huge practical difference, while keeping the exact same Java classification semantics.
## Wrap-up
Having a managed multimodal decision model in the Gemini API closes the loop on what I started experimenting with in September. Whenever your Java application needs fast, calibrated yes/no checks, multi-class routing, or rubric scoring across text, images, audio, video, or PDFs without burning output tokens, `gemini-decision-1` fits neatly into your backend.
Give both live editions a try with your own photos at [purrfect-match.cloud.run](https://purrfect-match.cloud.run) and [purrfect-match-gpu.cloud.run](https://purrfect-match-gpu.cloud.run), grab `io.github.glaforge:gemini-interactions-api-sdk:2.2.0` from Maven Central, and let me know on [GitHub](https://github.com/glaforge/gemini-interactions-api-sdk) what kind of routing or visual classification tasks you build with it!
# Evaluating ADK Java and Kotlin Agents with Dokimos
On Tuesday, I shared how I built FixSlidePic by [combining offline prompt benchmarking with an LLM-as-a-Judge loop]({{< ref "/posts/2026/11/10/restoring-lecture-slides-with-prompt-benchmarking-and-llm-as-judge.md" >}}) in [ADK for Java](https://github.com/google/adk-java).
For that project, I hacked together a standalone Python script to score prompt variants before writing the Java application.
Custom scripts get the job done once, yet as soon as you maintain several Java or Kotlin agents, you want those evaluations living in `src/test` and running with `mvn test` on every pull request.
That is what drew me to **[Dokimos](https://github.com/dokimos-dev/dokimos)**, an open-source (MIT) evaluation toolkit for LLM applications and AI agents in Java and Kotlin.
Dokimos already integrated with JUnit, LangChain4j, Spring AI, Koog, and Embabel, so I opened [PR #199](https://github.com/dokimos-dev/dokimos/pull/199) to contribute dedicated support for both **[ADK for Java](https://github.com/google/adk-java)** (`dokimos-adk-java`) and **[ADK for Kotlin](https://github.com/google/adk-kotlin)** (`dokimos-adk-kotlin`).
The pull request was merged earlier today and is already live on Maven Central in **[Dokimos 0.31.0](https://github.com/dokimos-dev/dokimos/releases/tag/v0.31.0)**.
> [!NOTE]
> **Links & coordinates at a glance:**
> - [Dokimos on GitHub](https://github.com/dokimos-dev/dokimos) and [PR #199](https://github.com/dokimos-dev/dokimos/pull/199)
> - [Google ADK integration documentation](https://dokimos.dev/integrations/adk)
> - Maven Central (`0.31.0`): `dev.dokimos:dokimos-adk-java:0.31.0` and `dev.dokimos:dokimos-adk-kotlin:0.31.0`
> - Runnable repository examples: [`AdkAgentEvaluationExample.java`](https://github.com/dokimos-dev/dokimos/blob/master/dokimos-examples/src/main/java/dev/dokimos/examples/adk/AdkAgentEvaluationExample.java) and [`AdkKotlinAgentEvaluationExample.kt`](https://github.com/dokimos-dev/dokimos/blob/master/dokimos-examples/src/main/kotlin/dev/dokimos/examples/adk/AdkKotlinAgentEvaluationExample.kt)
## Why Evaluating Agents Goes Beyond Final Text Answers
Traditional LLM tests compare a prompt against a final string answer.
With tool-calling and multi-agent workflows, a polite final reply can hide broken execution underneath:
1. An agent might call the wrong tool, pass an ungrounded parameter value that never appeared in the user's request, or violate the tool's JSON schema.
2. A tool might return a structured error payload (such as `{"error": "Impossible to look up..."}`) that the model glosses over.
3. A confused loop might call the same function three times with identical arguments, multiplying latency and token bills.
4. Sub-agents inside a sequential or parallel pipeline might skip a required step or pass incomplete coordinates downstream.
To catch these failure modes, Dokimos captures the full execution trace of an ADK run and feeds it to two families of evaluators:
```text
ADK Agent (LlmAgent / SequentialAgent / ParallelAgent)
│
├──► AdkSupport.toAgentTrace(...) or passive AdkTraceCollector plugin
│ ├── AgentTrace (finalResponse, toolCalls, reasoningSteps)
│ ├── List (names, descriptions, JSON schemas)
│ └── CallMetrics (tokensIn, tokensOut, latencyMs, costUsd)
│
└──► Dokimos Evaluators (dev.dokimos.core.evaluators.agents)
├── Deterministic checks (0 LLM calls, fast CI assertions)
└── JudgeLM checks (Gemini or any ADK BaseLlm / Model)
```
Five of Dokimos's nine agent evaluators are purely deterministic (no extra LLM calls or API costs), while the remaining four use a `JudgeLM` (or combine deterministic rule checks with optional LLM review):
| Evaluator | Type | What it checks |
| :--- | :--- | :--- |
| `ToolCallValidityEvaluator` | Deterministic | Validates every `ToolCall` against the JSON schemas in `metadata["tools"]` (tool exists, required arguments present, valid types/enums). |
| `ToolCorrectnessEvaluator` | Deterministic | Compares actual vs. expected tool calls (`NAMES_ONLY`, `NAMES_AND_ORDER`, or `NAMES_AND_ARGS`). |
| `ToolTrajectoryEvaluator` | Deterministic | Evaluates call sequences across `STRICT`, `IN_ORDER`, `ANY_ORDER`, `SUPERSET`, `SUBSET`, `PRECISION`, or `RECALL` modes. |
| `ToolErrorEvaluator` | Deterministic | Flags blank tool outputs, top-level JSON `"error"` fields, or custom error predicates. |
| `ToolEfficiencyEvaluator` | Deterministic | Computes the ratio of distinct `(name, args)` calls to total calls (`1.0` means zero duplicate calls). |
| `TaskCompletionEvaluator` | `JudgeLM` | Scores whether the agent fulfilled each user task listed in `metadata["tasks"]` (and optional `constraints`). |
| `ToolArgumentHallucinationEvaluator` | `JudgeLM` | Checks that every argument passed to a tool is grounded in the user's input. |
| `ToolNameReliabilityEvaluator` | Rules + optional `JudgeLM` | Audits tool names for `snake_case`, conciseness, and intent clarity. |
| `ToolDescriptionReliabilityEvaluator` | Rules + optional `JudgeLM` | Audits tool descriptions and parameter schemas for missing types or ambiguous wording. |
## Adding `dokimos-adk-java` to a Maven Project
Both ADK integrations declare the ADK SDKs as `provided` dependencies, so you keep whatever ADK version your project already uses (Java 17+ minimum).
Here is the Maven setup with Dokimos `0.31.0` and `dokimos-junit`:
```xml
com.google.adkgoogle-adk1.12.0dev.dokimosdokimos-adk-java0.31.0testdev.dokimosdokimos-junit0.31.0test
```
Because `dokimos-adk-java` hooks into ADK's `BaseLlm`, `Runner`, `Event`, and `BasePlugin` abstractions, it works with Gemini models as well as third-party models wrapped through `google-adk-langchain4j`, `google-adk-spring-ai`, or `Claude`.
## Testing a Single-Agent Tool Caller: Stock Ticker
To try `dokimos-adk-java` on real agent code, I started with the `_20_StockTicker` agent from my [`glaforge/ai-agent-protocols`](https://github.com/glaforge/ai-agent-protocols) repository.
It exposes a `lookup_stock_ticker` function via ADK's `@Schema` annotation and `FunctionTool.create(...)`, returning USD quotes for known tickers and a JSON `"error"` map whenever someone asks for an unknown ticker such as `"DEVOXX"`:
```java
import com.google.adk.agents.LlmAgent;
import com.google.adk.models.BaseLlm;
import com.google.adk.tools.Annotations.Schema;
import com.google.adk.tools.FunctionTool;
import java.util.Locale;
import java.util.Map;
public final class StockTickerAgent {
private static final Map QUOTES = Map.of(
"GOOG", "290.63", "GOOGL", "293.45", "ALPHABET", "290.63",
"NVDA", "173.73", "NVIDIA", "173.73",
"MSFT", "521.12", "MICROSOFT", "521.12");
public static LlmAgent create(BaseLlm model) {
return LlmAgent.builder()
.name("20-stock-ticker")
.description("Stock exchange ticker expert")
.model(model)
.instruction("""
You are a stock exchange ticker expert.
When asked about the stock price of a company,
use the `lookup_stock_ticker` tool to find the information
and report the stock price clearly in USD.
""")
.tools(FunctionTool.create(StockTickerAgent.class, "lookupStockTicker"))
.build();
}
@Schema(
name = "lookup_stock_ticker",
description = "Lookup stock price for a given company or ticker")
public static Map lookupStockTicker(
@Schema(
name = "company_name_or_stock_ticker",
description = "The company name or stock ticker to lookup")
String ticker) {
if (ticker == null || ticker.isBlank()) {
return Map.of("error", "Impossible to look up the stock price for " + ticker);
}
String normalized = ticker.trim().toUpperCase(Locale.ROOT);
String price = QUOTES.get(normalized);
if (price == null) {
return Map.of("error", "Impossible to look up the stock price for " + ticker);
}
return Map.of("ticker", normalized, "stock_price", price, "currency", "USD");
}
}
```
### Passive Trace, Schema, and Cost Capture with `AdkTraceCollector`
You can run an agent directly with `AdkSupport.toAgentTrace(agent, query)`, or attach `AdkTraceCollector` (an ADK `BasePlugin`) to your `Runner.Builder`.
Attaching the plugin has a nice perk: ADK passes the live `BaseTool` instance into tool callbacks, so `AdkSupport.toToolDefinitions(collector)` preserves every tool's description and JSON parameter schema automatically.
Here is an end-to-end JUnit test running against **Gemini 3.8 Flash** (`gemini-3.8-flash`), combining deterministic tool checks, `JudgeLM` checks (`AdkSupport.asJudge(gemini)`), and USD cost tracking through a `PriceTable`:
```java
Gemini gemini = Gemini.builder()
.modelName("gemini-3.8-flash")
.apiKey(System.getenv("GEMINI_API_KEY"))
.build();
LlmAgent agent = StockTickerAgent.create(gemini);
JudgeLM judge = AdkSupport.asJudge(gemini);
Runner.Builder runnerBuilder = Runner.builder().agent(agent).appName("stock-ticker-live");
AdkTraceCollector collector = AdkSupport.attach(runnerBuilder);
Runner runner = runnerBuilder.build();
String query = "What is Alphabet's current stock price? Please look up ticker GOOG.";
AgentTrace trace = AdkSupport.toAgentTrace(runner, query);
List tools = AdkSupport.toToolDefinitions(collector);
PriceTable flashPrices = (model, in, out) -> (in * 0.15 + out * 0.60) / 1_000_000.0;
CallMetrics metrics = collector.callMetrics("gemini-3.8-flash", flashPrices);
EvalTestCase testCase = EvalTestCase.builder()
.input(query)
.actualOutputs(trace.toOutputMap())
.expectedOutput(
"toolCalls",
List.of(ToolCall.of(
"lookup_stock_ticker",
Map.of("company_name_or_stock_ticker", "GOOG"))))
.metadata("tools", tools)
.metadata("tasks", List.of(
"Look up the stock price for GOOG",
"Report the stock price in USD"))
.build();
Assertions.assertEval(
testCase,
ToolCallValidityEvaluator.builder().build(),
ToolCorrectnessEvaluator.builder()
.matchMode(ToolCorrectnessEvaluator.MatchMode.NAMES_AND_ARGS)
.build(),
ToolErrorEvaluator.builder().build(),
ToolArgumentHallucinationEvaluator.builder().judge(judge).build(),
TaskCompletionEvaluator.builder().judge(judge).threshold(0.8).build());
```
Running this test against Gemini 3.8 Flash prints every evaluator score along with token counts (summing `promptTokenCount`, `candidatesTokenCount`, and `thoughtsTokenCount` across non-partial events), wall-clock latency, and computed cost:
```text
=== Live Gemini 3.8 Flash StockTickerAgent Evaluation ===
Query: What is Alphabet's current stock price? Please look up ticker GOOG.
Observed tools: [lookup_stock_ticker]
Final response: The current stock price for Alphabet (GOOG) is **$290.63 USD**.
Tool Call Validity: 1.00 (1/1 tool calls are valid.)
Tool Correctness: 1.00 (1 of 1 actual and 1 of 1 expected tool calls matched (with arguments).)
Tool Error Free: 1.00 (1/1 tool calls succeeded.)
Arg Grounding: 1.00 (1/1 tool calls have grounded arguments.)
Task Completion: 1.00 (2/2 tasks completed.)
Call Metrics: tokensIn=465, tokensOut=125, latencyMs=5767, costUsd=$0.000145
```
### Catching Structured Tool Errors (`"DEVOXX"`)
Look at what happens when we ask `"What is the stock price for DEVOXX?"`.
Passing `"DEVOXX"` as `company_name_or_stock_ticker` is completely valid according to the tool's JSON schema, so `ToolCallValidityEvaluator` scores `1.0`.
`ToolErrorEvaluator`, on the other hand, inspects the `FunctionResponse` returned by `lookupStockTicker`, spots the top-level `"error"` key, and flags the failure right away:
```java
@Test
void catchesStructuredDevoxxToolErrorWhileSchemaRemainsValid() {
String query = "What is the stock price for DEVOXX?";
AgentTrace trace = AdkSupport.toAgentTrace(agent, query);
List tools = AdkSupport.toToolDefinitions(agent);
EvalTestCase testCase = trace.toTestCase(query, tools);
EvalResult validity = ToolCallValidityEvaluator.builder().build().evaluate(testCase);
EvalResult toolError = ToolErrorEvaluator.builder().build().evaluate(testCase);
assertThat(validity.success()).isTrue();
assertThat(validity.score()).isEqualTo(1.0);
assertThat(toolError.success()).isFalse();
assertThat(toolError.score()).isEqualTo(0.0); // "0/1 tool calls succeeded"
}
```
## Parameterized Golden Datasets in JUnit with `@DatasetSource`
Checking one query in isolation is useful when writing an agent, while regression suites work better with a versioned dataset.
With `dokimos-junit`, you can keep golden test cases in `src/test/resources/datasets/stock-queries.json`:
```json
{
"name": "stock-ticker-golden-dataset",
"examples": [
{
"input": "What is Alphabet's current stock price? Use ticker GOOG.",
"expectedOutputs": {
"toolCalls": [
{
"name": "lookup_stock_ticker",
"arguments": { "company_name_or_stock_ticker": "GOOG" }
}
]
},
"metadata": {
"tasks": [
"Look up the stock price for GOOG",
"Report the stock price in USD"
]
}
}
]
}
```
Then annotate a JUnit `@ParameterizedTest` with `@DatasetSource`:
```java
@ParameterizedTest
@DatasetSource("classpath:datasets/stock-queries.json")
void evaluatesGoldenDatasetWithDeterministicAndJudgeEvaluators(Example example) {
AgentTrace trace = AdkSupport.toAgentTrace(agent, example.input());
EvalTestCase testCase = EvalTestCase.builder()
.inputs(example.inputs())
.actualOutputs(trace.toOutputMap())
.expectedOutputs(example.expectedOutputs())
.metadata(example.metadata())
.metadata("tools", AdkSupport.toToolDefinitions(agent))
.build();
Assertions.assertEval(
testCase,
ToolCallValidityEvaluator.builder().build(),
ToolCorrectnessEvaluator.builder()
.matchMode(ToolCorrectnessEvaluator.MatchMode.NAMES_AND_ARGS)
.build(),
ToolErrorEvaluator.builder().build(),
TaskCompletionEvaluator.builder().judge(judge).threshold(1.0).build());
}
```
Each entry in `stock-queries.json` shows up as an individual parameterized run in your IDE and CI test report.
For fast, deterministic unit tests that do not require an API key on every commit, you can also subclass ADK's `BaseLlm` with canned `FunctionCall` responses and reserve live Gemini runs for `@Tag("integration")` or `@EnabledIfEnvironmentVariable(named = "GEMINI_API_KEY", matches = ".+")`.
## Multi-Agent Trajectories: `SequentialAgent` and `ParallelAgent`
Single-agent tool calls are straightforward to assert in strict order.
Multi-agent pipelines (like [my Comic Trip agent]({{< ref "/posts/2026/03/30/building-my-comic-trip-agent-with-adk-java-1-0.md" >}}) or the geospatial emergency response workflow in [`glaforge/ign-agentic`](https://github.com/glaforge/ign-agentic)) introduce concurrency.
In `ign-agentic`, a `SequentialAgent` (`cellule-crise-ign`) coordinates three stages:
1. `agent-localisation` calls `geocode_address` to turn a French street alert into WGS84 coordinates.
2. A `ParallelAgent` (`collecte-territoriale-parallele`) runs `agent-topographe` (`get_elevation_and_slope`) and `agent-logistique` (`compute_isochrone`) concurrently on those coordinates.
3. `coordinateur-secours` synthesizes the terrain slope and 5-minute vehicle envelope into an intervention plan.
When I ran this pipeline twice in a row against Gemini 3.8 Flash, the two parallel branches finished in opposite orders:
- Run 1: `[geocode_address, get_elevation_and_slope, compute_isochrone]`
- Run 2: `[geocode_address, compute_isochrone, get_elevation_and_slope]`
A strict sequence assertion would fail roughly half the time!
This is where `AdkSupport.toToolDefinitions(pipeline)` (which recursively walks `subAgents()` across `SequentialAgent` and `ParallelAgent`), `Experiment`, and `ToolTrajectoryEvaluator` with `MatchMode.ANY_ORDER` fit together:
```java
// Recursively collects tools from SequentialAgent -> ParallelAgent -> LlmAgent sub-agents
List tools = AdkSupport.toToolDefinitions(pipeline);
// -> [geocode_address, get_elevation_and_slope, compute_isochrone]
ExperimentResult result = Experiment.builder()
.name("IGN Crisis Multi-Agent Evaluation")
.dataset(dataset)
.measuredTask(AdkSupport.measuredAgentTask(pipeline, "gemini-3.8-flash", flashPrices))
.evaluators(List.of(
ToolCallValidityEvaluator.builder().build(),
ToolErrorEvaluator.builder().treatBlankAsError(false).build(),
ToolTrajectoryEvaluator.builder()
.name("Parallel Crisis Trajectory")
.matchMode(ToolTrajectoryEvaluator.MatchMode.ANY_ORDER)
.argumentMatcher(ArgumentMatcher.of(ArgMatchMode.SUBSET))
.build()))
.build()
.run();
assertThat(result.passRate()).isEqualTo(1.0);
```
> [!TIP]
> **Two practical details to keep in mind:**
> 1. Unlike `ToolCorrectnessEvaluator` (which defaults to `NAMES_ONLY`), `ToolTrajectoryEvaluator` defaults to `ArgumentMatcher.tolerant()` (`ArgMatchMode.EXACT`). If your expected `ToolCall`s only specify a subset of arguments (or omit arguments with `Map.of()`), pass `ArgumentMatcher.of(ArgMatchMode.SUBSET)` or `ArgMatchMode.IGNORE` explicitly.
> 2. When two `ParallelAgent` branches emit concurrent `FunctionCall` events before either `FunctionResponse` arrives, event-window pairing in `measuredAgentTask` can leave one intermediate `ToolCall.result()` blank unless you attach `AdkTraceCollector` directly on the `Runner` or set `.treatBlankAsError(false)` on `ToolErrorEvaluator`.
## Idiomatic Kotlin Support with `dokimos-adk-kotlin`
Back in May, I wrote about [wiring ADK Kotlin agents into an Android app]({{< ref "/posts/2026/05/21/wiring-adk-kotlin-agents-in-an-android-application.md" >}}).
Even though Java is my home turf, I wanted Kotlin developers using [ADK for Kotlin](https://github.com/google/adk-kotlin) (`com.google.adk:google-adk-kotlin-core-jvm`) to get an integration tailored to coroutines rather than a Java wrapper.
ADK for Kotlin is a standalone, coroutine-native SDK built around `Flow`, `suspend` functions, `com.google.adk.kt.models.Model`, and `com.google.adk.kt.plugins.Plugin`.
Adding `dokimos-adk-kotlin` transitively pulls in `dokimos-kotlin` and its `experiment { ... }` DSL:
```kotlin
// build.gradle.kts
dependencies {
implementation("com.google.adk:google-adk-kotlin-core-jvm:1.4.0")
testImplementation("dev.dokimos:dokimos-adk-kotlin:0.31.0")
}
```
In package `dev.dokimos.adk.kt`, you get top-level extensions (`suspend fun BaseAgent.runTrace(input)`, `agent.toToolDefinitions()`, `gemini.asJudge()`, `agent.asConversationalApp()`) alongside automatic `modelId` resolution (since `LlmAgent.model.name` is public in ADK Kotlin):
```kotlin
import com.google.adk.kt.models.Gemini
import dev.dokimos.adk.kt.AdkSupport
import dev.dokimos.adk.kt.asJudge
import dev.dokimos.adk.kt.runTrace
import dev.dokimos.adk.kt.toToolDefinitions
import dev.dokimos.core.PriceTable
import dev.dokimos.core.agents.ToolCall
import dev.dokimos.core.evaluators.agents.ToolCorrectnessEvaluator
import dev.dokimos.kotlin.dsl.experiment
val gemini = Gemini(name = "gemini-3.8-flash", apiKey = System.getenv("GEMINI_API_KEY"))
val agent = createKotlinStockAgent(gemini)
val judge = gemini.asJudge()
// Inside a coroutine, you can also capture a single trace directly:
// val trace = agent.runTrace("What is NVIDIA's share price (NVDA)?")
val flashPrices = PriceTable { _, tokensIn, tokensOut ->
(tokensIn * 0.15 + tokensOut * 0.60) / 1_000_000.0
}
val result = experiment {
name = "Live ADK Kotlin Stock Evaluation"
dataset {
name = "live-kotlin-stock"
example {
input = "What is Microsoft's current stock price? Use ticker MSFT."
expected("toolCalls", listOf(ToolCall.of("lookup_stock_ticker", mapOf("ticker" to "MSFT"))))
metadata("tools", agent.toToolDefinitions())
metadata("tasks", listOf("Look up MSFT stock price", "State the price in USD"))
}
}
// modelId is inferred automatically from agent.model.name
asyncTask(AdkSupport.asyncAgentTask(agent, priceTable = flashPrices))
evaluators {
toolCallValidity()
toolCorrectness {
matchMode = ToolCorrectnessEvaluator.MatchMode.NAMES_AND_ARGS
}
toolError()
taskCompletion(judge) {
threshold = 0.8
}
}
}.run()
```
Running that Kotlin experiment against Gemini 3.8 Flash executes the coroutine `Flow` asynchronously, returns the `$521.12 USD` quote for Microsoft, scores all four evaluators at `100%`, and records `tokensIn=343, tokensOut=126, latencyMs=4110, costUsd=$0.000127`.
## Beyond Tool Calls: RAG and Multi-Turn Simulations
Tool trajectories are only half the story when testing conversational or knowledge-grounded agents.
Both `dokimos-adk-java` and `dokimos-adk-kotlin` also wire into Dokimos's RAG and multi-turn simulation APIs:
1. Calling `AdkSupport.ragTask(agent)` (or `measuredRagTask` / `asyncRagTask`) extracts retrieved chunks from both Gemini's built-in `GroundingMetadata` (`retrievedContext`, `ragChunk`, `web`) and retrieval tool `FunctionResponse` maps (`VertexAiRagRetrieval` or your own search tools), populating `"context"` for `FaithfulnessEvaluator` and `ContextualRelevancyEvaluator`.
2. Calling `AdkSupport.asConversationalApp(agent)` (or `agent.asConversationalApp()` in Kotlin) adapts any ADK agent for `ConversationSimulator`, letting an `LLMSimulatedUser` drive multi-turn persona scenarios across an ADK `Session` and produce a `ConversationTrajectory`.
## Wrap-up
Having deterministic tool assertions, `JudgeLM` rubrics, golden datasets, and per-run token cost tracking directly inside JUnit makes iterating on ADK prompts and sub-agent graphs much less guesswork.
You can assert tool schemas and trajectories for free on every commit, and run live Gemini judge evaluations before shipping prompt or model updates.
To try it on your own agents, grab `dev.dokimos:dokimos-adk-java:0.31.0` or `dev.dokimos:dokimos-adk-kotlin:0.31.0` from Maven Central, browse the [ADK integration documentation](https://dokimos.dev/integrations/adk), and check out the runnable Java and Kotlin samples in [`dokimos-examples`](https://github.com/dokimos-dev/dokimos/tree/master/dokimos-examples/src/main).
If you give it a spin on your ADK workflows, let me know what evaluators or patterns you find most useful!
# Restoring Skewed Lecture Slides: Prompt Benchmarking Meets LLM-as-a-Judge in ADK Java
Back in June, I wrote about [vibe-coding a Philosophy Bac prep app]({{< ref "/posts/2026/06/14/how-i-vibecoded-a-philosophy-prep-app-with-ai-studio-and-gemini.md" >}}) to help my daughter revise her handwritten flashcards before her high school exams.
She passed, and she is now in her first year of medical school.
Med school comes with a new set of study habits.
In several of her courses (cell biology, biochemistry, histology), professors project dense slides packed with Western blots, fluorescence microscopy, and molecular structures, **but do not share the slide decks with students**.
Seated in a large amphitheater, she does what every student does: she snaps quick photos of the projector screen with her phone, hoping to print them out later as clean study handouts.
If you have ever tried printing photos taken in a lecture hall or at a tech conference, you know how painful the result is:
- The slide is skewed at an angle and surrounded by beige amphitheater walls, speaker arrays, digital clocks, and emergency exit signs.
- Projector bulbs and ambient room lighting leave the slide washed out, turning high-contrast fluorescence microscopy into muddy beige squares.
- At conferences, you also run into curved cinema screens, DLP projector rainbow banding, live speech-to-text caption bars projected above or below the slide, and speakers or plants standing right in front of a diagram.
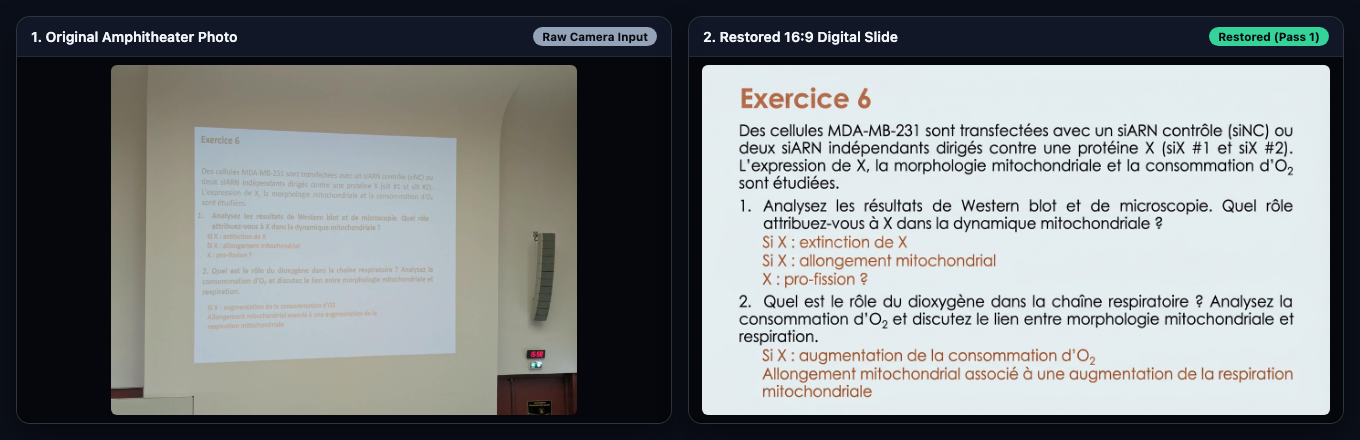
I wanted to build a web application, **[FixSlidePic](https://github.com/glaforge/fixslidepic)**, where she could drop a batch of lecture photos from her phone or laptop and get back a clean, flat, 16:9 PDF deck ready to print, just as if the professor had exported the original slides.
> [!NOTE]
> **Tech stack at a glance:**
> - **Source code**: [github.com/glaforge/fixslidepic](https://github.com/glaforge/fixslidepic)
> - **Backend**: [Micronaut 5.2.5](https://micronaut.io/) (Java 25) + [Apache PDFBox 3.0.7](https://pdfbox.apache.org/) for multi-slide PDF export
> - **Agent orchestration**: [ADK for Java 1.14.0](https://google.github.io/adk-docs/) (`com.google.adk:google-adk:1.14.0`) using a `LoopAgent`
> - **Models**: **Nano Banana 2.1** (`gemini-nano-banana-2.1`) for 16:9 slide restoration and **Gemini 3.8 Flash** (`gemini-3.8-flash`) as the multimodal LLM-as-a-Judge
> - **Deployment**: Containerized and deployed on [Google Cloud Run](https://cloud.google.com/run), with a Progressive Web App (PWA) frontend
> - **Built with**: [Google Antigravity](https://antigravity.google/)
Building this application turned into an interesting exercise in evaluating and hardening an agentic workflow at two levels:
1. I first ran an **offline prompt benchmark**, testing four prompt variations against a test set of difficult lecture and conference photos to find the best baseline instructions for Nano Banana 2.1.
2. I then wired a **runtime LLM-as-a-Judge inside an ADK `LoopAgent`**, pairing the image restoration agent with Gemini 3.8 Flash to inspect every restored slide against the original photo, score its fidelity, and trigger a fresh retry whenever a detail is missed.
## Why One-Shot Prompting Isn't Enough
When I first tested restoring slide photos manually with **Nano Banana 2.1** (`gemini-nano-banana-2.1`), the model did a great job unskewing perspective and redrawing readable text.
My initial handwritten prompt (`v1_baseline`) was five lines long:
```text
Improve the contrast so that this picture is readable.
Make the background white, but keep the color of the text or of boxes.
If the image is skewed or distorted, realign it properly.
Stay faithful to the original text, and don't change any letter or number.
I want to see the original slide that was presented on screen.
```
On simple white slides, that prompt worked fine.
Once I tested it on a broader mix of conference and amphitheater photos, two separate problems showed up.
First, my prompt had **systematic blind spots**.
Look at the second line: *"Make the background white, but keep the color of the text or of boxes."*
When a speaker uses a dark-mode slide deck, the model obeys literally, inverts the dark background to white, scrambles the contrast of colored pills, and introduces stray characters.
And when a conference projects live speech-to-text subtitles in a black bar right above the slide, the model assumes the subtitle bar is part of the slide header.
Second, generative image models make **occasional single-pass mistakes**.
Even with a carefully written prompt, the model might nail the perspective crop and 99% of a biochemistry slide on Pass 1, but turn carbon `1` into carbon `2` on a fructose ring, or leave a brownish projector tint on a microscopy panel.
In med school, a wrong carbon number on a glycosidic bond (`α1-β2`) is the difference between a right and wrong exam answer.
Fixing the systematic blind spots called for **offline prompt benchmarking** across a diverse test set.
Catching the single-pass mistakes called for **runtime verification with an LLM-as-a-Judge loop**.
## Part 1: Benchmarking Prompt Variants Against a Test Set
Before building the web UI, I assembled a folder of **29 slide photographs** in `test-pictures/` (combining my daughter's med school amphitheater photos with conference photos from Devoxx, JNation, and Google Cloud Summit).
From those 29 photos, I picked **5 torture-test images** covering the hardest failure modes:
| Test Case | Primary Challenge |
| :--- | :--- |
| **`dark_skew`** | Extreme 3D perspective skew + dark charcoal theme + two speakers & lectern in foreground |
| **`rainbow_subtitles`** | DLP projector rainbow color-wheel stripes + external live speech-to-text caption bar above slide + audience silhouettes |
| **`devoxx_split`** | Curved cinema screen + split-screen speaker camera feed on left + bottom sponsor/caption bar + complex architecture diagram |
| **`sketchnote_chrome`** | Dense hand-drawn sketchnote + Chrome browser tabs and URL bar at top + podium occlusion in bottom-right corner |
| **`led_occlusion`** | LED wall pixel-grid moiré + hanging spotlights + stage palm tree and speaker occluding the bottom banner text |
With Antigravity, I put together **4 prompt variants** and ran a parallel Python script (`run_benchmark.py`) invoking `gemini-nano-banana-2.1` across all `4 x 5 = 20` combinations, scoring every output with `gemini-3.8-flash` using a structured JSON rubric:
| Prompt Variant | Key Characteristics | Pass Rate (5 Torture Cases) | Avg Judge Score |
| :--- | :--- | :---: | :---: |
| **`v1_baseline`** | My initial manual prompt (*"Improve the contrast... Make the background white..."*) | **60% (3/5)** | **6.6 / 10** |
| **`v2_structured_restoration`** | Bullet-point instructions preserving original dark/light theme, removing stage/browser clutter, and inpainting occlusions | **100% (5/5)** | **7.4 / 10** |
| **`v3_digital_twin_rules`** | Numbered 5-rule "Digital Twin" specification | **80% (4/5)** | **6.8 / 10** |
| **`v4_calibrated_master` (Winner)** | 5-rule specification explicitly targeting live speech-to-text caption bars, DLP rainbow color-wheel stripes, split-screen video walls, and strict theme preservation | **100% (5/5)** | **7.4 / 10** *(Highest on hardest cases)* |
### What the Benchmark Revealed
Comparing the generated images side by side made it obvious why `v1_baseline` and `v3_digital_twin_rules` dropped points, and how `v4_calibrated_master` fixed them.
#### 1. Dark-Theme Inversion and Severe 3D Skew (`dark_skew`)
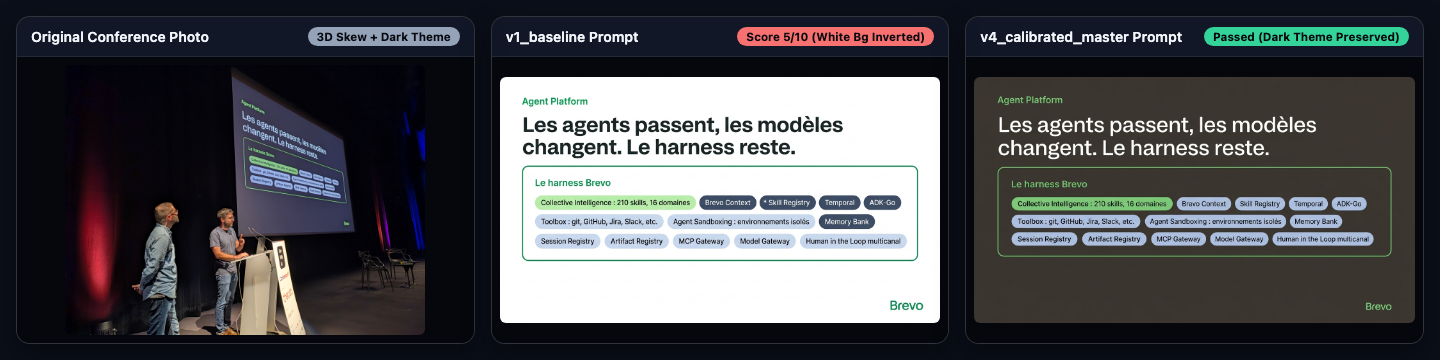
Because `v1_baseline` asked to *"make the background white"*, it forced a white background onto a dark charcoal slide, altered the container pill colors, and hallucinated a leading asterisk (`* Skill Registry` instead of `Skill Registry`).
In `v4_calibrated_master`, Rule 3 explicitly instructs the model to preserve the slide's authentic background theme (keeping dark slides dark and light slides light, without ever forcing a white background onto a dark-themed slide):
#### 2. The Meta Slide: DLP Rainbow Stripes & Projected Live Captions (`rainbow_subtitles`)
By a funny coincidence, one of the hardest photos in my conference folder was a slide about **AI Evaluation in 3 Steps** (*"1 - Simuler des inputs | 2 - Générer des outputs | 3 - Evaluer les outputs"*):
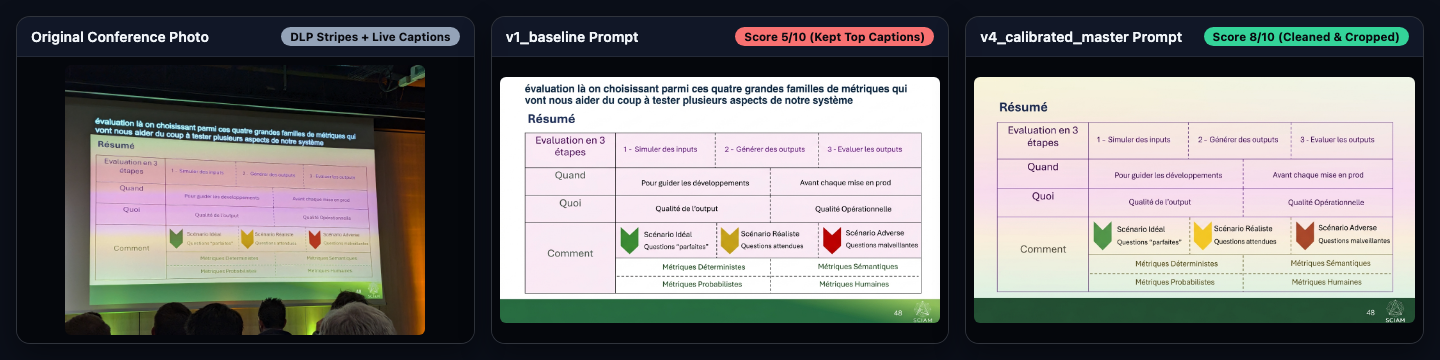
Look at the top of the original photo on the left: the conference room was projecting live French speech-to-text subtitles (*"évaluation là on choisissant parmi ces quatre grandes familles de métriques..."*) in a black strip directly above the slide's `Résumé` header.
At the same time, the DLP projector's spinning color wheel created pink, yellow, and green bands across the table.
Both `v1_baseline` and `v3_digital_twin_rules` mistook that projected subtitle strip for the title of the slide.
Once I saw that failure in the benchmark results, I updated Rule 1 and Rule 3 in `v4_calibrated_master` to explicitly exclude **live speech-to-text caption or subtitle bars projected above or below the slide** and neutralize **horizontal DLP projector rainbow/color-wheel banding**.
#### 3. Inpainting Foreground Occlusions: Speakers and Stage Palm Trees (`led_occlusion`)
At conferences, speakers move around on stage, and stage designers love putting plants and spotlights right in front of the screen.
On this Google Cloud Summit photo, a palm tree, a lectern, and the speaker overlapped the colored banner at the bottom of the slide (`"...e path to success and excellen..."`):
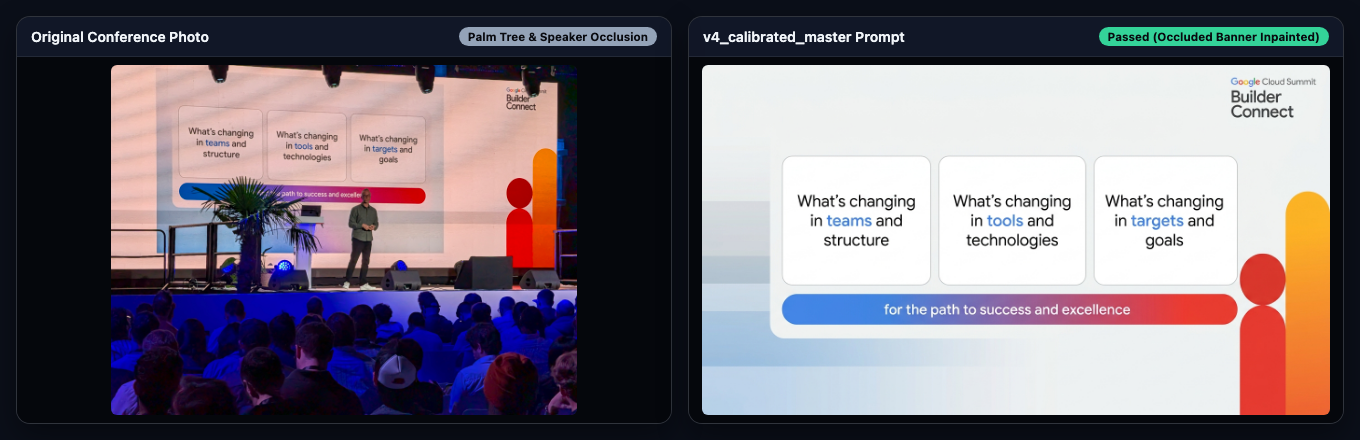
With Rule 4 (instructing the model to remove foreground obstructions like speakers, lecterns, plants, or stage lights and reconstruct the occluded shapes and text from context), `gemini-nano-banana-2.1` removed the audience, stage lights, palm tree, and presenter, cleaned up the LED wall moiré, and reconstructed the full banner text: **`"for the path to success and excellence"`**.
### The Winning Master Prompt (`v4_calibrated_master`)
Here is the 5-rule prompt that won the benchmark and now lives in `SlideFixerService.MASTER_SLIDE_RESTORATION_PROMPT`:
```text
Task: Extract and restore the presentation slide from this camera
photo into a clean, flat, high-resolution 16:9 digital slide as it
would appear directly on a computer screen.
Follow these 5 restoration rules strictly:
1. ISOLATE ONLY THE SLIDE CANVAS: Identify the exact boundaries of
the presentation slide itself. Crop out and exclude everything
outside the slide canvas: auditorium walls, stage, speakers,
podiums, audience heads, OS menu bars, browser tabs/URL bars,
conference video-wall split-screen feeds (such as live camera
feeds of the speaker), and any live speech-to-text caption or
subtitle bars projected above or below the slide.
2. GEOMETRIC RECTIFICATION: Correct all 3D perspective distortion,
keystone skew, tilt, and curved-screen warping so the slide is
perfectly rectangular, flat, and fills the 16:9 frame edge-to-edge.
3. COLOR & SURFACE PURIFICATION: Remove camera noise, DLP projector
rainbow/color-wheel banding (horizontal pink, magenta, yellow, or
green stripes across the screen), LED pixel-grid moire patterns,
screen glare, and uneven lighting. Neutralize projector color
bands completely so the slide background and table cells have
uniform, flat digital colors. Preserve the slide's authentic
background theme and color palette (keep dark/black slides dark,
light slides light, and colored/tinted slides faithful to the
original), and NEVER force a white background onto a dark slide.
4. INPAINT FOREGROUND OCCLUSIONS: If a speaker, lectern, microphone,
plant/palm tree, stage light, or silhouette overlaps part of the
slide canvas, cleanly remove the obstruction and reconstruct the
occluded slide background, shapes, and text from context.
5. VERBATIM TEXT & DIAGRAM FIDELITY: Reproduce every word, letter,
number, accent, URL, QR code, box, arrow, logo, and illustration
with 100% accuracy. Do not invent, paraphrase, summarize,
translate, or alter any text.
```
## Part 2: Runtime Self-Correction with ADK Java's `LoopAgent` and LLM-as-a-Judge
Offline benchmarking gave me a strong default prompt.
Still, when a med school slide has tiny chemical subscripts (`CH₂OH`, `α1-β2`) or low-contrast microscopy panels, the first generation pass can occasionally miss a detail.
Rather than returning the first generated image unchecked, I wrapped the restoration workflow in an **ADK for Java `LoopAgent`** (`com.google.adk:google-adk:1.14.0`) that runs up to **3 iterations**:
```text
User Upload
└──► ADK LoopAgent ("slide_restoration_loop", maxIterations = 3)
│
├──► 1. slide_fixer_agent (gemini-nano-banana-2.1)
│ Generates 16:9 slide from Original Photo
│ + Master Prompt (+ Judge Feedback)
│
└──► 2. slide_judge_agent (gemini-3.8-flash)
Compares Original Photo vs. Generated Slide
├─ satisfied == true ──► setEscalate(true) (Exit!)
└─ satisfied == false ──► Save instructions & retry
```
### Real Examples: Catching Subtle Med School Defects on Pass 1
This runtime `LoopAgent` proved its value right away when I tested my daughter's biochemistry and cell biology lecture photos.
#### Example 1: Fixing a Misnumbered Carbon Atom on a Sucrose Molecule
Look at this amphitheater photo of a biochemistry slide on **Saccharose (`D-Glucose + D-Fructose`)**:
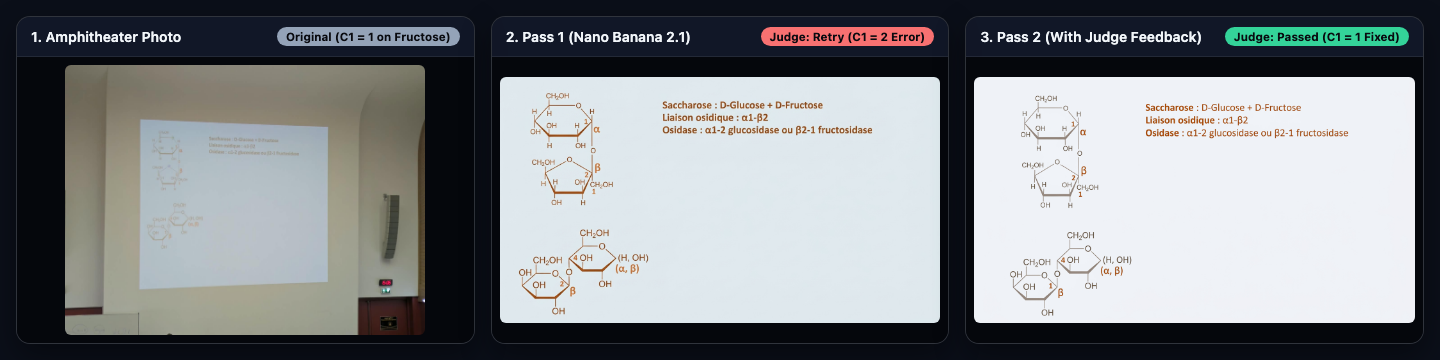
At first glance, **Pass 1** (middle panel) looks great: the beige amphitheater wall, speaker column, and red `15:06` clock are gone, and the Haworth projections are sharp.
Look closely at the bottom-left fructose ring in the lower Haworth projection, though (just to the left of the `β` label):
- In the **original photo** (left), the carbon atom participating in the glycosidic bond is labeled **`1`**.
- In **Pass 1** (middle), `gemini-nano-banana-2.1` wrote **`2`** instead of **`1`** inside that bottom-left ring.
- **`slide_judge_agent` (`gemini-3.8-flash`)** compared the two images, caught the numbering error, and emitted `rewrittenPromptInstructions` to fix the ring numbering and clean up the slight bluish tint.
- In **Pass 2** (right), `slide_fixer_agent` regenerated the slide from the original photo using the Judge's instructions, restoring the **`1`** label on the lower ring.
#### Example 2: Purifying Washed-Out Fluorescence Microscopy Panels
Here is another slide from the same lecture showing 6 fluorescence microscopy panels (`siNT (contrôle)`, `siMFN1 + siMFN2`, `siOPA1`, `Contrôle`, `DRP1 (surexpression)`, `DRP1-K38A (mutant GTPase-)`):
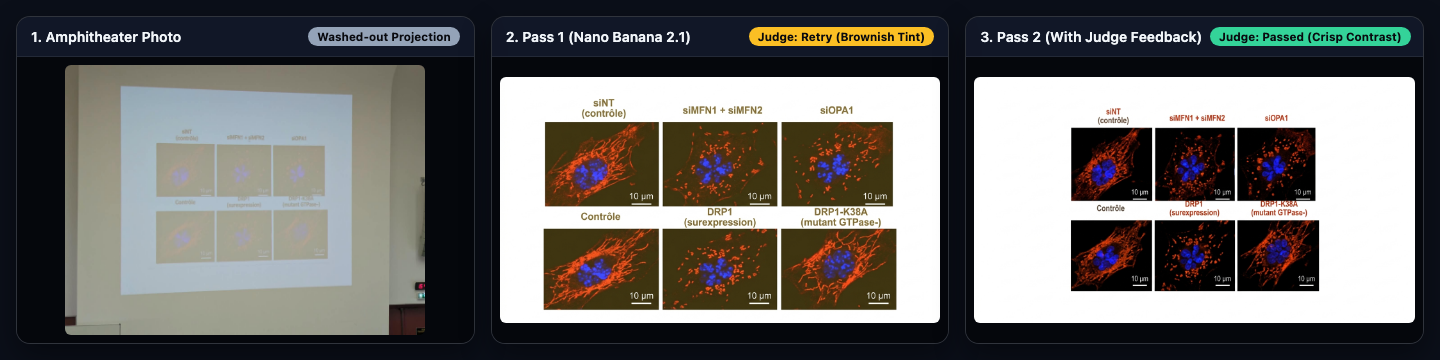
In the raw amphitheater photo (left), the room lights washed out the projector screen so badly that the black microscopy backgrounds looked pale tan.
On **Pass 1** (middle), `gemini-nano-banana-2.1` improved the contrast, but left a muddy brownish-olive tint inside the microscopy squares.
The Judge rejected Pass 1 and instructed the fixer to restore true black backgrounds inside the fluorescence microscopy panels while keeping the white slide canvas, producing the clean **Pass 2** result on the right.
### Implementing the `LoopAgent` in ADK for Java
Let's look at the code in [`SlideFixerService.java`](https://github.com/glaforge/fixslidepic/blob/main/src/main/java/io/github/glaforge/fixslidepic/service/SlideFixerService.java) and three details that make this loop work well in practice.
#### 1. Fresh Retry Grounding on the Original Photo (`beforeModelCallbackSync`)
A common trap in image-to-image refinement loops is feeding the *previous generated image* back into the image model on retry (`Photo -> Gen 1 -> Gen 2 -> Gen 3`).
Every generation pass compounds visual artifacts and drifts further away from the ground truth.
Instead, in `slide_fixer_agent`'s `beforeModelCallbackSync`, **every retry starts fresh from the original camera bytes** combined with the master prompt and the Judge's corrective instructions stored in the ADK session state:
```java
LlmAgent slideFixerAgent = LlmAgent.builder()
.name("slide_fixer_agent")
.model(createGeminiModel("gemini-nano-banana-2.1"))
.instruction(MASTER_SLIDE_RESTORATION_PROMPT)
.generateContentConfig(GenerateContentConfig.builder()
.responseModalities("IMAGE")
.imageConfig(ImageConfig.builder()
.aspectRatio("16:9")
.build())
.build())
.outputKey(STATE_LATEST_IMAGE_ID)
.beforeModelCallbackSync((callbackContext, llmRequestBuilder) -> {
String judgeFeedback = (String) callbackContext.state().get(STATE_JUDGE_FEEDBACK);
String userFeedback = (String) callbackContext.state().get(STATE_USER_FEEDBACK);
StringBuilder promptBuilder = new StringBuilder(MASTER_SLIDE_RESTORATION_PROMPT);
if (userFeedback != null && !userFeedback.isBlank()) {
promptBuilder.append("\n\nUSER REFINEMENT INSTRUCTIONS (HIGH PRIORITY):\n")
.append(userFeedback.trim());
}
if (judgeFeedback != null && !judgeFeedback.isBlank()) {
promptBuilder.append("\n\nCORRECTIVE INSTRUCTIONS FROM PREVIOUS JUDGE AUDIT (MUST FIX):\n")
.append(judgeFeedback.trim());
}
// Always ground the request on the ORIGINAL camera photograph + updated prompt
Content freshContent = Content.fromParts(
Part.fromBytes(record.originalBytes, record.originalMimeType),
Part.fromText(promptBuilder.toString())
);
llmRequestBuilder.contents(List.of(freshContent));
return Optional.empty();
})
// afterModelCallbackSync extracts the inline image bytes, saves the artifact,
// and stores the generated imageId in callbackContext.state()
.build();
```
#### 2. Structured Multimodal Judging and Early Loop Escalation
Next, `slide_judge_agent` uses **Gemini 3.8 Flash** (`gemini-3.8-flash`) with a JSON response schema (`JUDGE_SCHEMA`) that maps directly to a Java 25 record:
```java
@Serdeable
@JsonIgnoreProperties(ignoreUnknown = true)
public record JudgeVerdict(
boolean satisfied,
int overallScore,
int textFidelity,
int geometryAndCropping,
int themeAndVisualQuality,
String critique,
String rewrittenPromptInstructions
) {}
```
In `slide_judge_agent`, `beforeModelCallbackSync` passes both **IMAGE 1 (the original camera photo)** and **IMAGE 2 (the latest generated slide)** into the multimodal request.
Then, `afterModelCallbackSync` parses the `JudgeVerdict`. When `verdict.satisfied()` is `true`, it calls **`callbackContext.eventActions().setEscalate(true)`** to exit the `LoopAgent` right away without running unnecessary extra passes:
```java
LlmAgent slideJudgeAgent = LlmAgent.builder()
.name("slide_judge_agent")
.model(createGeminiModel("gemini-3.8-flash"))
.instruction(JUDGE_SYSTEM_INSTRUCTION)
.generateContentConfig(GenerateContentConfig.builder()
.responseMimeType("application/json")
.responseSchema(JUDGE_SCHEMA)
.build())
.outputKey("judge_verdict_json")
.beforeModelCallbackSync((callbackContext, llmRequestBuilder) -> {
String latestImageId = (String) callbackContext.state().get(STATE_LATEST_IMAGE_ID);
StoredImage latestImage = imageStore.get(latestImageId);
Content compareContent = Content.fromParts(
Part.fromText("IMAGE 1 - ORIGINAL CAMERA PHOTOGRAPH:"),
Part.fromBytes(record.originalBytes, record.originalMimeType),
Part.fromText("IMAGE 2 - GENERATED RESTORED SLIDE:"),
Part.fromBytes(latestImage.bytes(), latestImage.mimeType()),
Part.fromText("Evaluate IMAGE 2 against IMAGE 1 according to your rubric and return JSON.")
);
llmRequestBuilder.contents(List.of(compareContent));
return Optional.empty();
})
.afterModelCallbackSync((callbackContext, llmResponse) -> {
JudgeVerdict verdict = parseVerdict(extractText(llmResponse));
if (!verdict.rewrittenPromptInstructions().isBlank()) {
callbackContext.state().put(STATE_JUDGE_FEEDBACK, verdict.rewrittenPromptInstructions());
}
if (verdict.satisfied()) {
// Signal the ADK LoopAgent to exit early!
callbackContext.eventActions().setEscalate(true);
}
return Optional.empty();
})
.build();
LoopAgent slideRestorationLoop = LoopAgent.builder()
.name("slide_restoration_loop")
.subAgents(slideFixerAgent, slideJudgeAgent)
.maxIterations(3)
.build();
```
#### 3. Calibrating the Judge Rubric
One lesson I learned while testing the Judge is that **an uncalibrated LLM-as-a-Judge is either too nitpicky or too vague**.
Initially, `gemini-3.8-flash` would sometimes fail a clean restoration (`overallScore = 7`, `satisfied = false`) because a bullet point's font weight was slightly bolder than in the projector photo.
A retry cannot meaningfully improve sub-pixel font weight, and forcing an extra pass adds ~12 seconds of latency.
I added an explicit **Calibration Rubric** to `JUDGE_SYSTEM_INSTRUCTION` so the Judge only triggers a retry for **concrete, fixable defects**:
```text
Calibration Rubric:
- Set `satisfied = true` (and `overallScore` 8-10) if the slide is
clean, flat, readable, preserves the original theme and text
faithfully, and has no stage/browser/caption clutter or unremoved
obstructions. Minor differences in font weight, icon rendering, or
container padding are normal and SHOULD STILL PASS
(`satisfied = true`).
- Set `satisfied = false` (and `overallScore` <= 7) ONLY if there is
a concrete defect that a retry can fix: inverted background theme
(e.g. dark slide made white), uncropped live-caption/subtitle bar
or browser chrome, remaining stage/speaker obstruction, remaining
perspective skew, or corrupted/missing slide text.
- When `satisfied = false`, provide `rewrittenPromptInstructions`:
specific, direct corrective instructions to append to the
restoration prompt on the next pass (starting fresh from the
original photo) to fix the exact defect(s).
```
## Part 3: The FixSlidePic Web Application
With the prompt benchmarked and the `LoopAgent` calibrated, I wrapped everything in a responsive **Micronaut 5** web application (and installable **Progressive Web App**) built for quick study sessions.
### Real-Time SSE Progress & Parallel Batching
When my daughter finishes a two-hour lecture, she does not just have one photo; she has a dozen or more photos from the session.
Uploading and restoring 15 slides sequentially one by one would take several minutes.
So I added **multi-file drag-and-drop with parallel batching**, restoring up to 4 slides concurrently (backed by a fixed 4-thread pool on the Micronaut controller and a 4-worker pool in the browser):
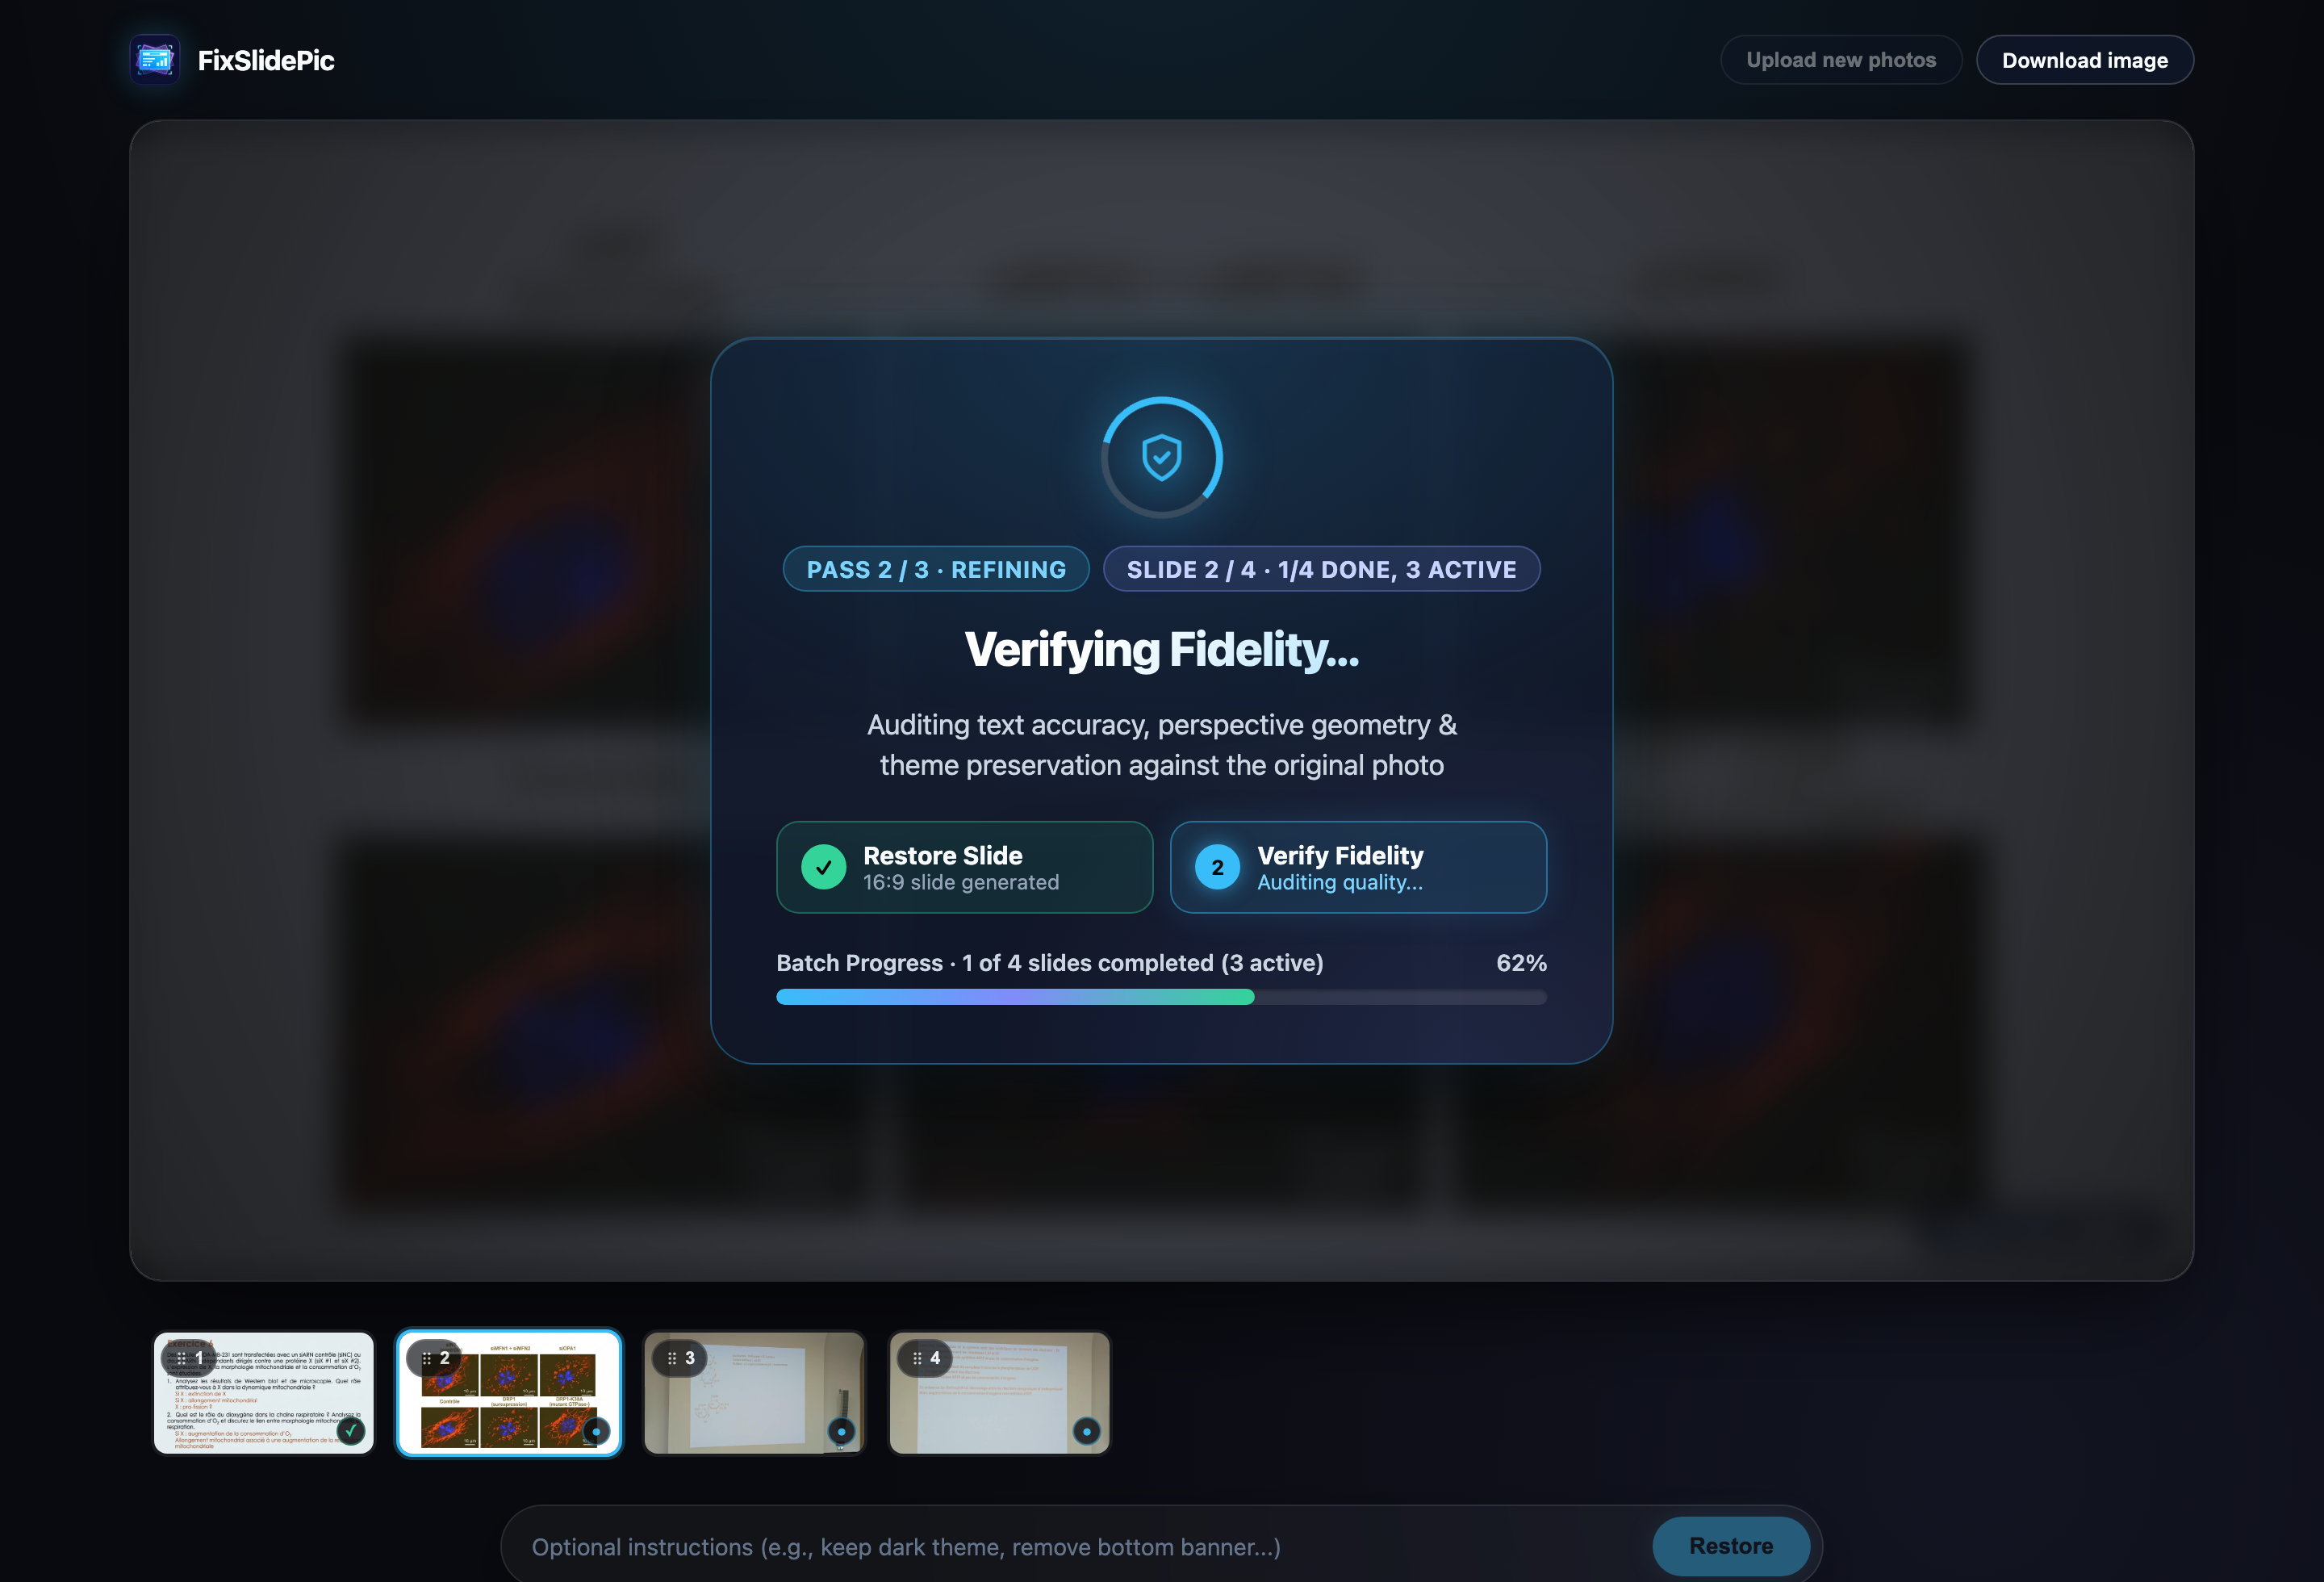
As each slide moves through the `LoopAgent`, the Micronaut `/api/slides/fix-stream` endpoint streams real-time **Server-Sent Events (`text/event-stream`)** to the browser (`FIXER_STARTED`, `FIXER_COMPLETED`, `JUDGE_STARTED`, `JUDGE_COMPLETED`, `LOOP_FINISHED`), updating the stage progress popup (`Pass 2 / 3 · Refining`, `Slide 2 / 4 · 1/4 done, 3 active`, the two-step `Restore Slide` / `Verify Fidelity` pipeline cards, and the overall batch progress bar) as well as the filmstrip thumbnails at the bottom.
### Inspecting Passes, Peeking at the Original, and Exporting to PDF
Once the batch finishes, the app automatically assembles all the restored 16:9 slides into a single multi-page **PDF document** (using **Apache PDFBox**) and triggers the download (`Download PDF (4 slides)`):
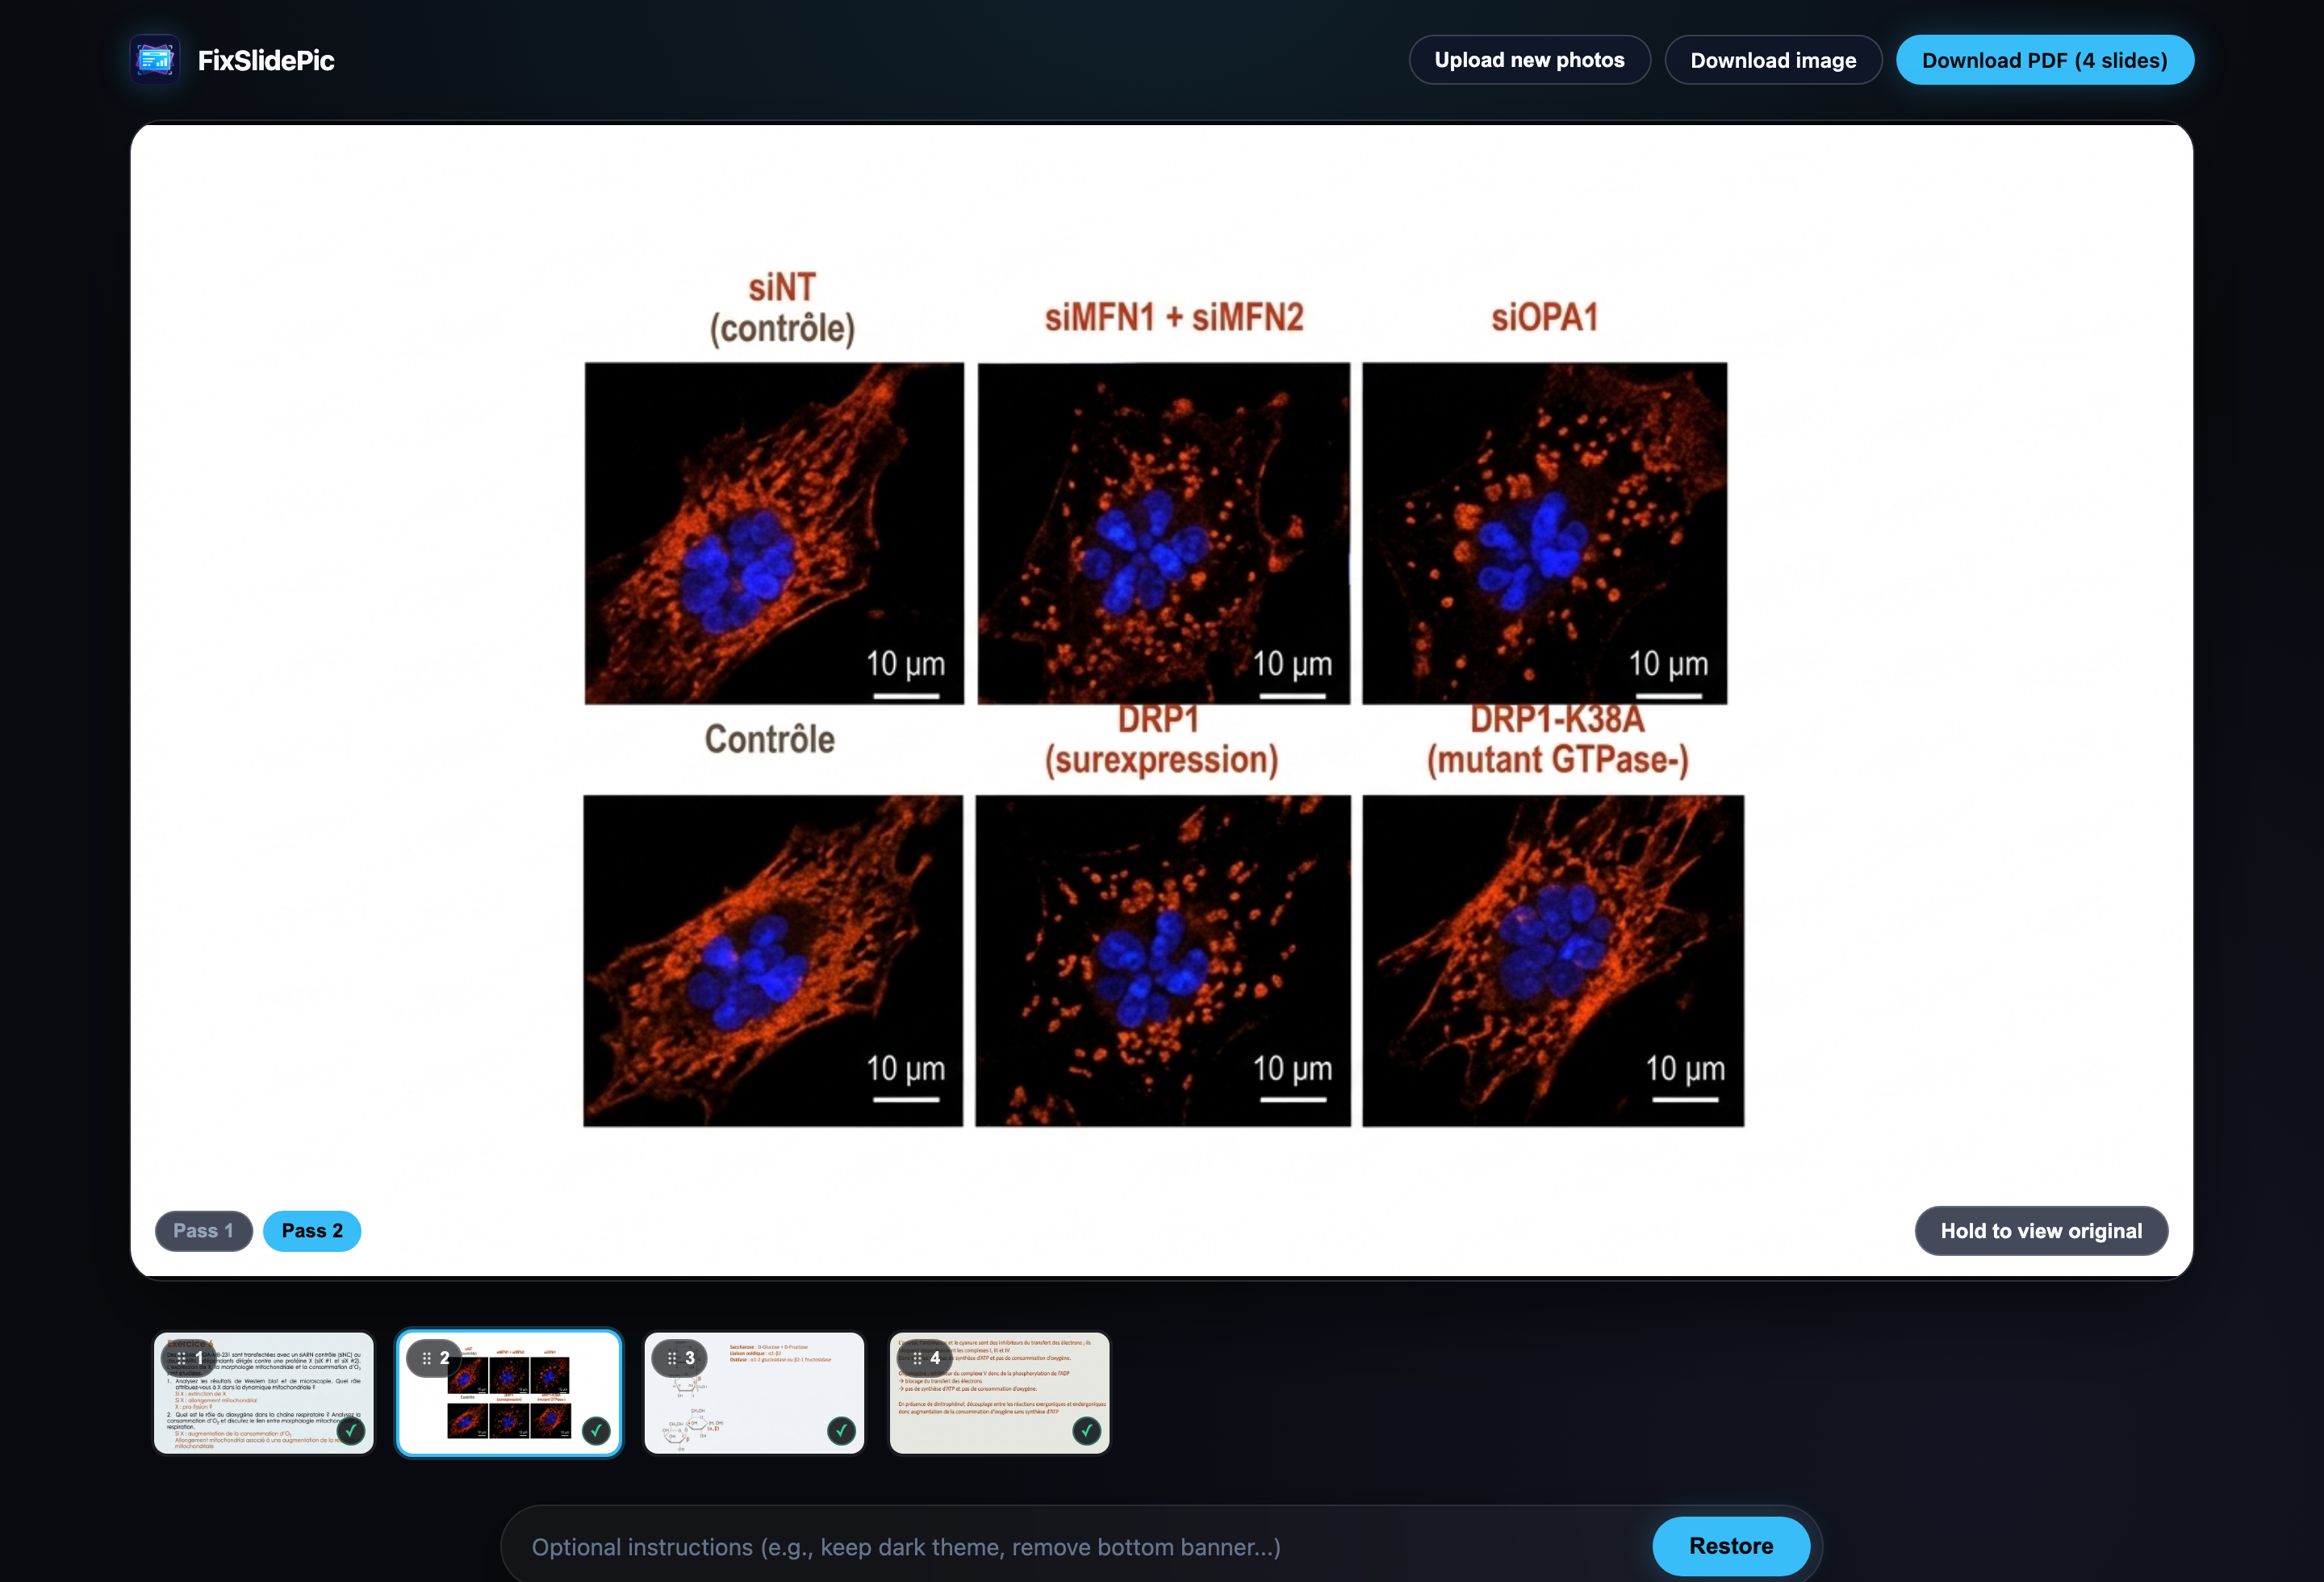
For any slide in the filmstrip, you can switch between `Pass 1` and `Pass 2` using the pills in the bottom-left corner of the stage to see what the `LoopAgent` improved between iterations.
You can also press and hold **"Hold to view original"** in the bottom-right corner to compare the raw amphitheater photo with the restored 16:9 slide in place, or type optional instructions in the bottom bar (for instance, *"keep dark background inside the microscopy squares"*) and click **Restore** to run another pass through the `LoopAgent`.
## Wrap-up
Combining offline prompt benchmarking with an online LLM-as-a-Judge loop turned out to be a very practical recipe:
- **Offline benchmarking** across a small, representative torture-test set catches systematic prompt flaws (like inverting dark-mode slides or keeping projected live-caption bars) before you write application code.
- **Runtime self-correction** with **Nano Banana 2.1** (`gemini-nano-banana-2.1`) and **Gemini 3.8 Flash** (`gemini-3.8-flash`) inside an **ADK Java `LoopAgent`** catches stochastic single-pass mistakes (like a misnumbered carbon atom on a sucrose ring) and exits early via `setEscalate(true)` as soon as the output passes inspection.
- **Fresh retry grounding** in `beforeModelCallbackSync` (always passing the original camera photo + the Judge's rewritten instructions rather than chaining generated images) prevents multi-generation drift.
Most importantly, my daughter now has clean, readable PDF handouts for her med school lectures!
You can browse the full source code on GitHub at [glaforge/fixslidepic](https://github.com/glaforge/fixslidepic).
If you are building multimodal or agentic pipelines with [ADK for Java](https://google.github.io/adk-docs/), let me know how you approach prompt evaluation and runtime judging in your own projects.
# Comparing Java Formatters: Why Open Java Format Is My New Favorite
Recently, I read Alex Abashev's article on Foojay.io, [My love-hate relationship with Java formatters](https://foojay.io/today/my-love-hate-relationship-with-java-formatters/).
Unlike Go with `gofmt` or Rust with `rustfmt`, Java has never shipped a built-in source code formatter in the JDK, leaving teams to argue in pull requests over Checkstyle rules, IntelliJ XML exports, or where the dot goes in a stream pipeline.
In his post, Alex made two points that immediately resonated with me:
1. Once you experience an opinionated, zero-configuration formatter as a CI gate, you never want to go back to bikeshedding over indentation in code reviews.
2. **AI coding agents make deterministic formatters matter more than ever.** Every model and every session has its own idea of code style, regardless of what you write in your [`AGENTS.md` or `GEMINI.md` files]({{< ref "/posts/2026/11/02/automating-monday-morning-sdk-updates-with-antigravity.md" >}}). One agent puts every method parameter on its own line, another crams a whole stream pipeline into a 200-character line, and a third reformats untouched methods, turning a two-line bug fix into a 400-line whitespace diff.
In his article, Alex also introduced [open-java-format](https://openjavaformat.dev/) ([GitHub](https://github.com/openjavaformat/open-java-format)), an open-source fork of `palantir-java-format` that he created to fix long-standing bugs, modernize the build and IDE tooling, and keep pace with recent JDK releases.
That made me curious: how do the main Java formatters actually compare today on modern Java 21 to 25 code?
I put together a test and benchmark suite on JDK 25 (`25.0.4.1.1`) across 16 targeted Java snippets and a 1,042-line `FormatterShowcase.java` file covering 86 formatting scenarios, pitting five formatters against each other:
1. **[Google Java Format](https://github.com/google/google-java-format)** (`2.0.0`, released October 30, 2026, alongside legacy `1.37.0`)
2. **[Palantir Java Format](https://github.com/palantir/palantir-java-format)** (`2.103.0`)
3. **[Open Java Format](https://github.com/openjavaformat/open-java-format)** (`21.0.2`)
4. **[Prince of Space](https://github.com/agustafson/prince-of-space)** (`2.3.1`)
5. **[Netflix jfmt](https://github.com/Netflix/jfmt)** (`0.9.0`)
Along the way, I uncovered some surprising edge-case bugs (including a compilation-breaking annotation bug in Prince of Space reported at [Issue #147](https://github.com/agustafson/prince-of-space/issues/147), and a 2-cycle oscillation crash in Netflix's `jfmt` on empty blocks with comments), and contributed a backward-compatibility fix to Open Java Format ([PR #200](https://github.com/openjavaformat/open-java-format/pull/200), already merged and released in `21.0.2`) as well as a pull request to Spotless ([PR #3179](https://github.com/diffplug/spotless/pull/3179)).
> [!NOTE]
> **Quick links to the projects and articles:**
> - **Trigger article:** [My love-hate relationship with Java formatters](https://foojay.io/today/my-love-hate-relationship-with-java-formatters/) by Alex Abashev on Foojay.io
> - **Open Java Format:** [openjavaformat.dev](https://openjavaformat.dev/), [GitHub repository](https://github.com/openjavaformat/open-java-format), and [WebAssembly Playground](https://openjavaformat.dev/playground/)
> - **Other formatters:** [google-java-format](https://github.com/google/google-java-format), [palantir-java-format](https://github.com/palantir/palantir-java-format), [prince-of-space](https://github.com/agustafson/prince-of-space), and [Netflix/jfmt](https://github.com/Netflix/jfmt)
## The Five Contenders at a Glance
Before looking at code diffs, here is how the five formatters compare across their core design choices:
| Dimension | `google-java-format` (`2.0.0`) | `palantir-java-format` (`2.103.0`) | `open-java-format` (`21.0.2`) | `prince-of-space` (`2.3.1`) | `Netflix/jfmt` (`0.9.0`) |
| :--- | :--- | :--- | :--- | :--- | :--- |
| **Maven Coordinates** | `com.google.googlejavaformat:google-java-format:2.0.0` | `com.palantir.javaformat:palantir-java-format:2.103.0` | `dev.openjavaformat:open-java-format:21.0.2` | `io.github.agustafson.princeofspace:prince-of-space-core:2.3.1` | `com.netflix:com.netflix.tools.jfmt:0.9.0` |
| **Parser Engine** | Internal `jdk.compiler` (`javac` AST) | Internal `jdk.compiler` (`javac` AST) | Internal `jdk.compiler` (`javac` AST) | **JavaParser** (`3.28.2`, no internal JDK APIs) | Internal `jdk.compiler` (`javac` AST + attribution in `ImportNormalizer`; forked from GJF `1.36.1`) |
| **Minimum JDK** | JDK 21+ | JDK 21+ | JDK 21+ | JDK 17+ | **JDK 25+** (classfile version `69.0`) |
| **Requires `--add-exports` on JVM?** | **Yes** (6 `--add-exports`) | **Yes** (`--add-exports` + `--add-opens`) | **Yes** on JVM (native binaries need none) | **No** (runs on standard JVM classpath) | **Yes** (7 `--add-exports`, including `com.sun.tools.javac.model`) |
| **Default Line Length** | **100** cols (`--max-line-length` added in 2.0.0) | **120** cols | **120** cols | **120** cols (configurable) | **Unlimited** (`UNLIMITED_LINE_WIDTH`; wraps by **AST structural complexity**; **80** cols for Javadoc) |
| **Default Indentation** | **2 spaces** (4sp continuation; `AOSP` = 4/8) | **4 spaces** (8sp continuation) | **4 spaces** (8sp continuation) | **4 spaces** (8sp continuation; 4sp for chains) | **4 spaces** (8sp continuation + **column alignment** up to 24-space cap) |
| **Configurability** | Minimal (`GOOGLE`/`AOSP`, `--max-line-length`, `--cleanup=false`) | Minimal (`PALANTIR`/`GOOGLE`/`AOSP`, `formatJavadoc`) | Minimal (`OJF`/`PALANTIR`/`GOOGLE`/`AOSP`, `formatJavadoc`) | **7 options** (`indentStyle`, `indentSize`, `lineLength`, `wrapStyle`, `closingParenOnNewLine`, `trailingCommas`, `javaLanguageLevel`) | **Zero style flags** (CLI offers `--check`, `-` stdin, and `javac` flags `-cp`, `-p`, `--source-path`) |
| **Single-Arg Block Lambda** | **Inline** in `2.0.0` (wrapped in `1.37.0`) | **Inline** | **Inline** | **Inline** | **Inline** |
| **Multi-Arg Trailing Block Lambda** | **Wraps** all arguments | **Inline** (`call(a, () -> {`) | **Inline** (`call(a, () -> {`) | **Inline** (`call(a, () -> {`) | **Inline** (`call(a, () -> {`) |
| **Method Chain Wrapping** | Breaks at 100 cols; `.stream()` stays on receiver | Breaks at **80-col dot limit** or 120-col line limit; 8sp indent | Same as Palantir (80-col dot limit, 120-col line limit, 8sp indent) | Breaks at 120 cols; **breaks before `.stream()`**; 4sp indent | Breaks by AST complexity; `.stream()` stays on variable receiver and **column-aligns** chained `.` under `.stream()` |
| **Braceless `if`/`else`/`for`/`while`** | Preserves braceless statements | Preserves braceless statements | Preserves braceless statements | **Inserts `{ ... }` braces** | **Inserts `{ ... }` braces** (`ControlBraces`) |
| **Import Sorting & Unused Removal** | **Yes** | **Yes** | **Yes** (preserves `import java.lang.*` with wildcards) | **No** | **Yes** (**4 OpenJDK groups** + CLI semantic `ImportNormalizer` expanding `import pkg.*;` and shortening `pkg.Type`) |
| **Partial Range Formatting** | **Yes** | **Yes** | **Yes** | **No** (whole-file only) | **Yes** (via internal `Formatter.formatSource`) |
| **JBang `//DEPS` & `//$NON-NLS-1$`** | Breaks (`// DEPS`, `// $NON-NLS-1$`) | Breaks (`// DEPS`, `// $NON-NLS-1$`) | **Preserves exact syntax** | Preserves `//DEPS`, moves `//$NON-NLS-1$` | Preserves standalone `///usr/bin/env` & `//DEPS`, breaks trailing `// $NON-NLS-1$` |
| **GraalVM Native / Wasm** | Native binaries on GitHub Releases | Native binaries (Linux/macOS) | Native binaries + **WebAssembly** ([Playground](https://openjavaformat.dev/playground/)) | JVM JAR / CLI fat JAR | Modular JAR (`ToolProvider` `"jfmt"`) + JDK 25 `jlink` image |
## How They Format Code Differently: Side-by-Side Examples
When I ran all five formatters across the 16 test snippets, `google-java-format`, `palantir-java-format` / `open-java-format`, `prince-of-space`, and `Netflix/jfmt` produced almost completely distinct layouts across families.
Even small differences in indentation, alignment, and wrapping philosophy change the visual shape of daily Java code.
### 1. Lambdas and Reactive / Async Pipelines
For years, the biggest complaint against `google-java-format` (`1.x`) was how it treated lambdas and method chains: it forced a line break right after the opening parenthesis of a method call taking a block lambda, creating deep "staircase" indentation.
On October 30, 2026, Google released **`google-java-format` `2.0.0`**, which finally keeps **single-argument** block lambdas inline (`executor.submit(() -> {`).
However, as soon as a method takes **more than one argument** (such as a context parameter or timeout alongside a trailing block lambda), `google-java-format` `2.0.0` still wraps every argument onto its own line:
```java
// google-java-format 2.0.0 (2-space indent, 100 columns)
public String multiArgTrailingBlockLambda(
RetryPolicy retryPolicy, String operationContextDescription) {
return retryPolicy.executeWithFallbackAndCircuitBreaker(
operationContextDescription,
() -> {
String raw = fetchData();
return transform(raw);
});
}
```
By contrast, `palantir-java-format`, `open-java-format`, `prince-of-space`, and `Netflix/jfmt` apply the "rectangle rule": they keep the leading argument and the `() -> {` lambda header on the same line as the call, so the block reads just like a built-in `if` or `for` statement:
```java
// palantir-java-format 2.103.0, open-java-format 21.0.2, prince-of-space 2.3.1 & Netflix/jfmt 0.9.0
public String multiArgTrailingBlockLambda(RetryPolicy retryPolicy, String operationContextDescription) {
return retryPolicy.executeWithFallbackAndCircuitBreaker(operationContextDescription, () -> {
String raw = fetchData();
return transform(raw);
});
}
```
### 2. Streams and Fluent Method Chains
Consider a medium-length stream pipeline (around 105 characters total):
```java
// palantir-java-format 2.103.0 & open-java-format 21.0.2
public List mediumChain(List items) {
return items.stream()
.filter(s -> s != null)
.map(String::trim)
.filter(s -> !s.isEmpty())
.toList();
}
```
Notice how differently the other formatters handle this exact pipeline:
- Even though the entire chain is 105 characters and would fit inside a 120-column limit, `palantir-java-format` and `open-java-format` wrap it onto one call per line because they enforce an **80-column dot limit** for chained calls. Short chains (`items.stream().filter(s -> !s.isEmpty()).toList()`) stay on one line, while multi-step pipelines break cleanly with `.stream()` attached to `items` and an 8-space continuation indent.
- If you run `google-java-format 2.0.0` with `--max-line-length=120`, it has no 80-column dot heuristic, so it flattens the entire 4-step `mediumChain` onto a single 105-character line.
- **`prince-of-space`** breaks *before* `.stream()` and indents chained calls by 4 spaces instead of 8:
```java
// prince-of-space 2.3.1
public List mediumChain(List items) {
return items
.stream()
.filter(s -> s != null)
.map(String::trim)
.filter(s -> !s.isEmpty())
.toList();
}
```
- **`Netflix/jfmt`** keeps `.stream()` attached when the receiver is a simple variable (`items.stream()`), and then uses `Indent.Align` (capped at 24 spaces) to **column-align** every subsequent `.filter(...)`, `.map(...)`, and `.toList()` dot directly under `.stream()` at column 20:
```java
// Netflix/jfmt 0.9.0 (dots column-aligned under .stream() at column 20)
public List mediumChain(List items) {
return items.stream()
.filter(s -> s != null)
.map(String::trim)
.filter(s -> !s.isEmpty())
.toList();
}
```
Because `Netflix/jfmt` wraps method chains based on AST structural complexity (`MAX_UNBROKEN_COMPLEXITY = 6`) rather than line length, it even wraps a 58-character 3-step chain (`items.stream().filter(s -> !s.isEmpty()).toList()`, complexity `7 > 6`) across three column-aligned lines, whereas the other four formatters keep it on one line.
### 3. Method Signatures, Closing Parentheses, and Structural Complexity Wrapping
When a method declaration or call overflows the line limit, `google-java-format`, `palantir-java-format`, and `open-java-format` bin-pack short parameters when they fit together on the continuation line (or place them one per line when they don't) and keep the closing `) {` inline after the last parameter:
```java
// palantir-java-format & open-java-format
public Map>>> orchestrateWorkflow(
String tenantIdentifier,
String workflowExecutionId,
List inputPayloadRecords,
boolean enableStrictValidation,
int maxConcurrencyLimit,
long timeoutMilliseconds) {
...
}
private Map>>> invokeDownstreamService(
String a, String b, List c, boolean d, int e, long f) {
return Map.of();
}
```
`prince-of-space` defaults to a Rust/Kotlin-inspired `BALANCED` wrapping style with `closingParenOnNewLine = true`: whenever a parameter or argument list wraps, every item is placed on its own line and the closing `) {` or `);` sits on a dedicated line aligned with the declaration:
```java
// prince-of-space 2.3.1 (default BALANCED style)
private Map>>> invokeDownstreamService(
String a,
String b,
List c,
boolean d,
int e,
long f
) {
return Map.of();
}
```
**`Netflix/jfmt`** takes the most radical approach of all: **it has no column width limit for code (`UNLIMITED_LINE_WIDTH = (1 << 28) - 1`, or 268,435,455 columns)** and removes `StringWrapper` completely so string literals are never split across lines (while still reflowing Javadoc and `///` Markdown doc comments at **80 columns**).
Instead of enforcing a fixed line-length limit, `jfmt` decides whether a parameter list, argument list, or expression is `FLAT` (single line), `WRAPPED` (single continuation break), or `BROKEN` (one per line) primarily from **AST structural complexity** (`MAX_UNBROKEN_COMPLEXITY = 6`, combined with syntax-width heuristics such as a long first argument):
- Every simple method parameter (`VariableTree`) has a structural complexity score of `2`. That means a method or constructor with **4 to 6 simple parameters** (complexity `8` to `12 > 6`) **wraps with a single continuation break before the 4th parameter** (`WRAPPED`), even if the entire signature is only 90 characters, while **7 or more simple parameters** (or fewer parameters with complex generic types/annotations) switch to one parameter per line (`BROKEN`)!
- Conversely, a 134-character 4-argument method call with inline `/* ... */` comments (complexity `4 <= 6`), a 137-character `@SuppressWarnings(value = "...")` annotation (complexity `3 <= 6`), or even a 436-character low-complexity statement stays on **one unbroken line**:
```java
// Netflix/jfmt 0.9.0:
// 134-character 4-arg call has complexity 4 (<= 6), so it stays on 1 unbroken line:
public void invokeWithInlineComments() {
configureEndpoint("https://api.example.com", null /* customAuthHeader */, true /* followRedirects */, 30_000 /* timeoutMs */);
}
// 90-character 4-param method has complexity 4 * 2 = 8 (> 6), so it always wraps before the 4th parameter:
private void configureEndpoint(String url, String header, boolean follow,
int timeout) {}
```
And if a wrapped 4-parameter method has a short name whose opening `(` sits at or before column 24, `jfmt` column-aligns the wrapped parameter under `(` (`public void op(String a, String b, String c,\n String d) {}`).
### 4. Braceless Control Flow and AST Cleanups
Historically, `google-java-format` refused to modify the AST beyond import ordering and modifier sorting.
That changed in **`google-java-format` `2.0.0`**, which now runs an AST cleanup pass by default (disableable via `--cleanup=false`) that:
- Removes redundant double semicolons (`;;` becomes `;`),
- Strips empty annotation parentheses (`@Deprecated()` becomes `@Deprecated`),
- Removes parentheses around single untyped lambda parameters (`(s) -> s.trim()` becomes `s -> s.trim()`),
- Reorders modifiers to JLS order (`static public final` becomes `public static final`).
Both **`prince-of-space`** and **`Netflix/jfmt`** (via `ControlBraces.addBraces`) go even further on control flow: if they encounter a braceless `if`, `else`, `for`, or `while` statement (`if (value < 0) return "negative";`), they automatically insert `{ ... }` curly braces around the body. The Google/Palantir/Open Java Format family leaves braceless statements untouched.
## Performance and Idempotency Benchmarks on JDK 25
To measure how fast each formatter runs in-process on the JVM and how compact their outputs are, I benchmarked all five formatters (plus legacy `google-java-format` `1.37.0`) on JDK 25 (`25.0.4.1.1`) across:
- **16 targeted comparison snippets** (25 warmup iterations + 50 timed iterations)
- **`FormatterShowcase.java`** (a 1,042-line torture test covering 86 Java 21 to 25 formatting scenarios; 10 warmup iterations + 25 timed iterations)
| Formatter | Cold 1st Call (ms) | 16-Snippet Suite Avg (ms) | `FormatterShowcase` (1,042 lines) Avg (ms) | Showcase Output Lines | Showcase Max Line Length | Showcase Avg Line Length | 1st-Pass Idempotent on Showcase? |
| :--- | ---: | ---: | ---: | ---: | ---: | ---: | :---: |
| `google-java-format` `2.0.0` | 162.5 | 13.4 | 41.0 | 1,566 | 153 | 38.9 | **No** (converges on pass 2) |
| `google-java-format` `1.37.0` | 19.4 | 12.2 | 38.8 | 1,580 | 153 | 38.9 | **No** (converges on pass 2) |
| `palantir-java-format` `2.103.0` | 36.3 | 13.9 | 65.4 | 1,479 | 157 | 45.8 | **Yes** |
| `open-java-format` `21.0.2` | 27.6 | 14.6 | 98.8 | 1,479 | 157 | 45.8 | **Yes** |
| `prince-of-space` `2.3.1` | 87.4 | 8.5 | 73.1 | 1,598 | 156 | 42.0 | **Yes** |
| `Netflix/jfmt` `0.9.0` | 52.9 | 11.8 | 33.7 *(1st pass; public API fails)* | 1,397 *(pass 1)* | **436** | 48.1 | **No** (2-cycle oscillation crash!) |
Three numbers stand out in this table:
1. **Vertical compactness (with bounded line width):** Among formatters that enforce a 100- or 120-column line limit, `palantir-java-format` and `open-java-format` format the 1,042-line showcase into **1,479 lines** (averaging 45.8 characters per line), saving nearly 90 vertical lines compared to `google-java-format` (`1,566` lines) and 120 lines compared to `prince-of-space` (`1,598` lines).
2. **`Netflix/jfmt`'s speed vs. 436-column lines and convergence:** On the 16-snippet suite (where all formatters converge cleanly), `Netflix/jfmt` is the fastest `javac`-based formatter at `11.8 ms` because it removes `StringWrapper` (no extra re-lex/re-parse pass for long strings) and sets `UNLIMITED_LINE_WIDTH`, eliminating width-overflow backtracking. On `FormatterShowcase.java`, however, its public `JfmtFormatter.formatSource` API fails after 8 passes due to a 2-cycle oscillation bug (detailed below); inspecting a single internal `Formatter.formatSource` pass takes `33.7 ms` and produces 1,397 lines, but with low-complexity statements stretching up to **436 characters** on a single line.
3. **`open-java-format` vs. `palantir-java-format` on long strings:** Across the 16 normal snippets, `open-java-format` and `palantir-java-format` run at virtually the same speed (~14 ms). On `FormatterShowcase.java` (which includes several intentionally oversized string literals), `open-java-format` averages ~99 ms vs. ~65 ms for Palantir. Bytecode inspection of `com.palantir.javaformat.java.StringWrapper` shows why: `open-java-format` wraps `StringWrapper.wrapOnce(...)` in a convergence loop (`MAX_ROUNDS = 5`). Whenever a pass splits or joins a long string literal, it runs an extra verification pass to guarantee that the output is 100% stable on the first call.
## Pros, Cons, and the Bugs I Found
Let's look at the strengths, trade-offs, and bugs I hit when testing each formatter.
### 1. Google Java Format (`2.0.0`)
**Pros:**
- The closest thing to a de facto standard in the Java world, with first-class support across every build tool and IDE.
- The `2.0.0` release (October 30, 2026) fixes single-argument block lambdas, adds `--max-line-length=N`, and introduces the AST cleanup pass.
- Reflows both classic `/** ... */` HTML Javadoc comments and Java 23+ JEP 467 `///` Markdown doc comments out of the box.
**Cons & Gotchas:**
- 2-space indentation and a 100-column line limit feel cramped on modern wide monitors (and while `--aosp` switches to 4-space indentation, it still wraps multi-argument lambdas).
- When `Formatter.formatSourceAndFixImports` wraps a string literal longer than 100 columns, `StringWrapper` indents the continuation `+ "..."` relative to the start column of the string (e.g., 15 spaces in `return "..."`), whereas a second pass re-indents that binary `+` expression to the standard 8-space continuation indent. In other words, `format(x) != format(format(x))` on the first pass!
- It corrupts JBang headers and Eclipse `$NON-NLS$` comments: `///usr/bin/env jbang` becomes `/// usr/bin/env jbang` (breaking shell execution) and `//DEPS` becomes `// DEPS` (which JBang ignores). It also turns `//$NON-NLS-1$` into `// $NON-NLS-1$` because `JavaCommentsHelper` compiled its exemption regex with a double-escaped backslash (`"^//+(noinspection|\\\\$NON-NLS-\\\\d+\\\\$)"`), matching a literal backslash followed by end-of-line instead of `$NON-NLS-1$`!
### 2. Palantir Java Format (`2.103.0`)
**Pros:**
- Created specifically to solve Google Java Format's vertical staircase problem on modern monitors: 4-space indentation, 120-column line width, the "rectangle rule" for lambdas, and an 80-column dot limit for readable fluent chains.
- Fast (~65 ms on the 1,042-line `FormatterShowcase.java`) and 1st-pass idempotent.
**Cons & Gotchas:**
- As Alex noted in his Foojay article, external issues and PRs often sit unreviewed because releases primarily track Palantir's internal infrastructure syncs.
- Like `google-java-format`, `palantir-java-format` breaks JBang scripts (`/// usr/bin/env jbang`, `// DEPS`) and Eclipse `// $NON-NLS-1$` comments.
- I also verified three subtle formatting bugs in `2.103.0` that are still present upstream:
- `StringWrapper.getReflowReplacements` hardcodes a 4-space continuation indent (`12` spaces inside a method) instead of `4 * indentationMultiplier` (`16` spaces), which leaks into the output whenever 16 spaces would push a wrapped string segment past column 120.
- When a file contains a wildcard import (such as `import java.util.concurrent.*;`), `palantir-java-format` unconditionally strips explicit `import java.lang.Thread;` imports, which can cause a compilation error if the wildcard package defines a type with the same simple name.
- A leading line comment inside a multi-resource `try (` header is dedented to the same column as `try (` instead of the resource continuation indent.
### 3. Prince of Space (`2.3.1`)
**Pros:**
- Built on **JavaParser** (`3.28.2`) rather than internal `jdk.compiler` classes, so you can embed it in any standard JVM application or tool without `--add-exports` flags.
- Exposes 7 configuration options (`indentStyle`, `indentSize`, `lineLength`, `wrapStyle`, `closingParenOnNewLine`, `trailingCommas`, and `javaLanguageLevel`).
**Cons & Gotchas:**
- Does not sort imports or remove unused imports, does not reflow Javadoc or `///` comments, does not support partial character-range formatting, and normalizes `\r\n` (CRLF) line endings to `\n`.
- `FormatterConfig.defaults()` sets `JavaLanguageLevel.of(17)`, which fails to parse Java 21 pattern switch guards and Java 25 flexible constructor bodies unless you explicitly configure `JavaLanguageLevel.of(21)` or `of(25)`.
- In switch expression assignments (`String label = switch (code) { case 1 -> "one"; ... };`), `prince-of-space` wraps `switch (code) {` to 16 spaces while indenting `case 1 ->` at only 12 spaces (leaving the cases less indented than their enclosing `switch`).
- **Showstopper annotation bug ([Issue #147](https://github.com/agustafson/prince-of-space/issues/147)):** During my testing with JSpecify nullability annotations, I discovered that when a method combines declaration annotations before `public` (`@Deprecated @SuppressWarnings(...)`) with a type-use annotation after `public` (`public @Nullable String`), `prince-of-space` `2.3.1` duplicates `@SuppressWarnings` into the return type position:
```java
// Broken output from prince-of-space 2.3.1 (fails to compile!)
@Deprecated
@SuppressWarnings({"unchecked", "rawtypes"})
public @SuppressWarnings({"unchecked", "rawtypes"}) @Nullable String findRecord(
```
Because `java.lang.SuppressWarnings` is not `@Repeatable`, **`javac` refuses to compile the formatted code** (`SuppressWarnings is not a repeatable annotation interface`). I reported this upstream at [agustafson/prince-of-space#147](https://github.com/agustafson/prince-of-space/issues/147).
### 4. Netflix `jfmt` (`0.9.0`)
**Pros:**
- Forked from `google-java-format` `1.36.1` with all internal dependencies (`google-java-format`, Guava, CommonMark, JSpecify) shaded under `com.netflix.tools.jfmt.internal.*`, so it has zero classpath conflict with `google-java-format` or Guava.
- Opinionated 4-space OpenJDK-inspired style with inline single-arg and multi-arg trailing block lambdas, column-aligned `.stream()` pipelines, automatic `{ ... }` braces on single-statement control flow (`ControlBraces`), and 80-column reflowing for both classic `/** ... */` Javadoc and Java 23+ `///` Markdown doc comments.
- Preserves standalone JBang headers (`///usr/bin/env jbang`, `//DEPS`, `//JAVA`) verbatim because it disables line-comment reflowing (`wrapLineComments = false`).
- **Two-tier import normalization:**
1. Sorts imports into **4 OpenJDK groups** (`import module`, `java.*`/`javax.*`, third-party, and `import static`) and preserves comment-divided import blocks intact instead of failing with `error: Imports not contiguous` like `google-java-format` and `palantir-java-format`.
2. When invoked on files via the `jfmt` CLI (`JfmtToolProvider`), `ImportNormalizer` runs `JavacTaskImpl.parse()` and `JavacTaskImpl.enter()` to **expand wildcard imports** (`import java.util.*;` becomes explicit `import java.util.List;`, etc.) and **shorten unambiguous fully-qualified type names in code** (`java.time.Duration` in a method signature becomes `Duration` + `import java.time.Duration;`).
**Cons & Gotchas:**
- **JDK 25+ only:** `com.netflix:com.netflix.tools.jfmt:0.9.0` is compiled to classfile version `69.0` (JDK 25) and requires 7 `--add-exports` flags on `jdk.compiler` (adding `com.sun.tools.javac.model`).
- **Unbounded line lengths vs. premature parameter wrapping:** Because `jfmt` sets `UNLIMITED_LINE_WIDTH` and removes `StringWrapper`, low-complexity statements and string literals can stretch to 200 to 436+ columns on a single line, while a 75-character method with 4 short parameters wraps onto two lines simply because its AST complexity is `4 * 2 = 8 > 6`.
- **`jfmt` CLI requires `-cp` / `-p` on non-modular files with third-party imports:** Because `ImportNormalizer` runs `JavacTaskImpl.enter()` on input files, running `jfmt` on a non-modular `.java` file that imports third-party libraries without passing `--class-path` (`-cp`) or `--module-path` (`-p`) aborts with a `javac` `package ... does not exist` error (exit code `1`). (If an enclosing `module-info.java` is passed alongside the file and its required modules are missing, `ImportNormalizer` gracefully falls back to syntax-only formatting; passing `-` to format via stdin also skips `ImportNormalizer`.)
- **Minor comment glitches:** When the last row of an array initializer has a trailing line comment (`0, 0, 1 // row 2`), `jfmt` indents the closing `};` by 8 spaces instead of 4:
```java
public static final int[] MATRIX_ROWS = {
1, 0, 0, // row 0
0, 1, 0, // row 1
0, 0, 1 // row 2
};
```
And while standalone `//DEPS` comments are preserved, trailing same-line `//$NON-NLS-1$` comments still get an extra space (`// $NON-NLS-1$`).
- **Showstopper non-convergence bug (`Formatting did not converge`) on empty blocks containing a block comment (`{ /* ... */ }`):** In `jfmt` `0.9.0`, `Doc.Break.computeWidth()` was modified from `isForced() ? MAX_LINE_WIDTH : flat.length()` to `isForced() ? 0 : flat.length()`. Combined with `UNLIMITED_LINE_WIDTH`, any empty method or block body containing a single-line block comment (such as `@Override public void close() { /* cleanup */ }` in Scenario 19 of `FormatterShowcase.java`) **oscillates in a 2-cycle on every pass**:
```java
// Pass 1 (when input has a space before /* cleanup */):
public void close() {
/* cleanup */
}
// Pass 2 (when input has a newline between { and /* cleanup */):
public void close() {/* cleanup */
}
```
Pass 3 reverts to Pass 1! Because `JfmtFormatter.formatSource(String)` (and the `jfmt` CLI) runs an 8-pass convergence loop and throws if the output does not stabilize, **running `new JfmtFormatter().formatSource(...)` or the `jfmt` CLI on `FormatterShowcase.java` (or any file containing `{ /* comment */ }`) crashes with `FormatterException: error: Formatting did not converge`**.
## Why Open Java Format (`21.0.2`) Is My New Favorite
`open-java-format` takes everything that made `palantir-java-format` pleasant to read (4-space indentation, 120-character lines, inline trailing lambdas, and clean stream chains) and fixes the sharp edges, while turning the project into a responsive, community-friendly open-source tool.
### 1. Fixing the Sharp Edges
In my JUnit 5 comparison suite, `open-java-format` (`21.0.2`) and `palantir-java-format` (`2.103.0`) produce byte-for-byte identical output on normal code, except where `open-java-format` fixes real bugs:
1. **First-class JBang and `$NON-NLS$` support:** Since I frequently write self-contained scripts and [coding agents with JBang]({{< ref "/posts/2026/04/11/a-simple-coding-agent-in-a-loop-with-langchain4j-jbang-and-gemini.md" >}}), this alone is a huge relief. `open-java-format` preserves `///usr/bin/env jbang`, `//DEPS`, `//JAVA`, `//SOURCES`, and `//FILES` directives verbatim:
```java
// open-java-format 21.0.2 preserves JBang headers and $NON-NLS$ markers intact:
///usr/bin/env jbang "$0" "$@" ; exit $?
//DEPS com.google.guava:guava:33.7.2-jre
//JAVA 25+
package demo;
public class JbangAndComments {
/*** Banner comment that is not a Javadoc comment ***/
public static void main(String... args) {
String greeting = "Hello World"; //$NON-NLS-1$
System.out.println(greeting);
}
}
```
Whereas both `google-java-format` and `palantir-java-format` turn that into:
```java
// google-java-format & palantir-java-format break JBang and $NON-NLS$, and strip the blank line after /*** ... ***/:
/// usr/bin/env jbang "$0" "$@" ; exit $?
// DEPS com.google.guava:guava:33.7.2-jre
// JAVA 25+
package demo;
public class JbangAndComments {
/*** Banner comment that is not a Javadoc comment ***/
public static void main(String... args) {
String greeting = "Hello World"; // $NON-NLS-1$
System.out.println(greeting);
}
}
```
2. **Joining adjacent same-line string literals:** When developers or coding agents write `"Hello " + "world"` on a single line (or in generated `toString()` methods), `open-java-format` automatically merges them into `"Hello world"`, so the formatted output no longer depends on where someone arbitrarily split a string literal.
3. **Consistent 16-space string reflow:** Fixes Palantir's 12-space vs. 16-space continuation indent leak in `StringWrapper`, re-wrapping long strings until they converge cleanly within 120 columns.
4. **Safe `java.lang` import handling & `try (` comments:** Retains explicit `import java.lang.Thread;` when wildcard imports are present, and properly indents leading comments inside `try (` headers.
### 2. Contributing `Style.PALANTIR` Compatibility (`PR #200`) and Spotless Support (`PR #3179`)
To make migration painless, `open-java-format` kept the `com.palantir.javaformat.*` Java package names so existing plugins and callers can swap the Maven coordinates (`dev.openjavaformat:open-java-format`) as a drop-in replacement.
However, when I tested `open-java-format` `21.0.1` against tools that invoke the formatter reflectively (like Spotless's `PalantirJavaFormatStep`), I noticed a hitch: `open-java-format` had renamed the enum constant `JavaFormatterOptions.Style.PALANTIR` to `Style.OJF`.
Any caller executing `Style.valueOf("PALANTIR")` or referencing `Style.PALANTIR` threw an `IllegalArgumentException` or `NoSuchFieldError`.
I opened [openjavaformat/open-java-format#200](https://github.com/openjavaformat/open-java-format/pull/200) to restore `Style.PALANTIR` as a `@Deprecated` alias of `Style.OJF` with identical formatting and import-ordering behavior.
Alex reviewed, merged, and released it in **`open-java-format` `21.0.2`** almost immediately.
In parallel, I also opened [diffplug/spotless#3179](https://github.com/diffplug/spotless/pull/3179) to allow overriding the `groupArtifact` on Spotless's `palantirJavaFormat` step.
## Configuring and Using the Formatters
Let's look at how to set up and configure `open-java-format` across your CLI, build tools, IDEs, and AI coding workflows, followed by how to configure `google-java-format`, `palantir-java-format`, `prince-of-space`, and `Netflix/jfmt` if you want to use or compare them in your own projects.
### 1. Open Java Format: CLI, Gradle, Maven, IDEs, and AI Agents
You can try `open-java-format` right in your browser without installing anything using the [interactive Playground](https://openjavaformat.dev/playground/), which compiles the formatter to WebAssembly using GraalVM Web Image.
#### Command Line (Native Binary or Runnable JAR)
Every release publishes pre-built GraalVM native binaries (~60 MB, zero JVM startup overhead, no `--add-exports` flags needed) for Linux (`x86_64`, `aarch64`), macOS (Apple Silicon and Intel), and Windows (`x86_64`), plus a self-contained runnable `-all.jar`.
On macOS (Apple Silicon), for example:
```bash
curl -LO https://github.com/openjavaformat/open-java-format/releases/download/21.0.2/open-java-format-macos_aarch64
chmod +x open-java-format-macos_aarch64
mv open-java-format-macos_aarch64 /usr/local/bin/open-java-format
```
You can then format files in place or verify formatting in CI:
```bash
# Format all tracked Java files in place
open-java-format --replace $(git ls-files '*.java')
# Dry-run check for CI (exits with code 1 if any file is unformatted)
open-java-format --dry-run --set-exit-if-changed $(git ls-files '*.java')
```
#### Gradle (`dev.openjavaformat.java-format` & Spotless)
In a Gradle build (Gradle 9+ on Java 21+), apply the `dev.openjavaformat.java-format` plugin:
```groovy
// build.gradle
plugins {
id 'java'
id 'dev.openjavaformat.java-format' version '21.0.2'
}
repositories {
mavenCentral()
}
```
And enable the native formatter in `gradle.properties` so you do not need `--add-exports` on the Gradle daemon:
```properties
# gradle.properties
openjavaformat.native.formatter=true
```
Running `./gradlew formatDiff` formats only the lines you modified in `git diff HEAD`, and automatically configures `.idea/open-java-format.xml` when you open the project in IntelliJ IDEA.
If your Gradle build also uses **Spotless**, applying both plugins (`com.diffplug.spotless` and `dev.openjavaformat.java-format`) automatically wires `open-java-format` into `spotlessJava` (just remove any existing `palantirJavaFormat()` call from your `spotless` block, and add the `jdk.compiler` `--add-exports` flags shown below to `org.gradle.jvmargs` in `gradle.properties` since Spotless runs in-process on the Gradle JVM).
#### Maven (`fmt-maven-plugin`)
For Maven projects (running on Java 21+), `open-java-format` provides `dev.openjavaformat:fmt-maven-plugin` (a fork of Spotify's `fmt-maven-plugin`):
```xml
dev.openjavaformatfmt-maven-plugin2.27.0.2formatdev.openjavaformatopen-java-format21.0.2
```
The `format` goal runs automatically in the `process-sources` phase during `mvn compile` or `mvn test`, and you can run `mvn dev.openjavaformat:fmt-maven-plugin:check` in CI to fail the build if any file is not formatted.
#### IntelliJ IDEA and Eclipse Plugins
To get the exact same formatting on `Cmd+Option+L` (`Ctrl+Alt+L`) or on save in your IDE:
- **IntelliJ IDEA:** Install the [open-java-format plugin](https://plugins.jetbrains.com/plugin/34359-open-java-format) from the JetBrains Marketplace, go to **Settings > Tools > open-java-format Settings**, tick **Enable open-java-format**, and tick **Use native binary > Download**. With the native binary enabled in `21.0.2`, formatting a file in the IDE takes ~40 ms instead of ~430 ms because it does not spin up a new JVM process per file.
- **Eclipse:** Drop `open-java-format-eclipse-plugin-21.0.2.jar` from the GitHub release into your Eclipse `dropins` folder.
#### Wiring It Up for AI Coding Agents
As I discussed in my recent post on [Agent eXperience (AX)]({{< ref "/posts/2026/10/30/agent-experience-in-practice-serving-this-hugo-blog-as-markdown.md" >}}), giving AI coding agents (like [Antigravity](https://antigravity.google/) or Claude Code) fast, deterministic tools is far more reliable than hoping they follow prose instructions.
You can combine two lightweight guardrails in your repository:
1. **In `AGENTS.md` / `GEMINI.md`:** Tell the agent explicitly not to format Java code by hand and to invoke the CLI after editing:
````markdown
## Java formatting
Java code in this repository is formatted with `open-java-format` (120 columns, 4-space indentation, one fixed style).
Never lay out code by hand. After creating or editing a `.java` file, run:
```sh
open-java-format --replace path/to/File.java
```
````
2. **In an edit hook or CI:** If your agent supports post-edit hooks (like Claude Code's `PostToolUse` hook in `.claude/settings.json`), you can run `open-java-format --skip-removing-unused-imports --replace` automatically after every file edit in ~50 ms. And in GitHub Actions, once you commit a `.open-java-format-version` file (`echo 21.0.2 > .open-java-format-version`) at the root of your repository, a two-line step checks every pull request without even needing a JDK on the runner:
```yaml
- uses: actions/checkout@v7
- uses: openjavaformat/open-java-format-action@v4
```
### 2. Configuring Google Java Format, Palantir Java Format, Prince of Space, and Netflix `jfmt`
If you want to configure the other four formatters in Spotless, via their CLIs, or programmatically in Java, here are the exact configurations I used in my test suite.
#### Spotless (Gradle & Maven) for `google-java-format` and `palantir-java-format`
Both `google-java-format` and `palantir-java-format` have built-in steps in [Spotless](https://github.com/diffplug/spotless):
```groovy
// build.gradle
plugins {
id 'com.diffplug.spotless' version '8.0.0'
}
spotless {
java {
// Option A: Google Java Format 2.0.0
// Use .aosp() if you want 4-space indentation instead of 2-space
googleJavaFormat('2.0.0')
.reflowLongStrings()
.formatJavadoc(true)
// Option B: Palantir Java Format 2.103.0
// Set formatJavadoc(true) if you want classic /** ... */ Javadoc reflowed
// palantirJavaFormat('2.103.0').style('PALANTIR').formatJavadoc(true)
}
}
```
With `google-java-format` `2.0.0` on the command line (or via its native binary), you can also combine `--aosp` (4-space indentation), `--max-line-length=120`, and `--cleanup=false` (to disable the new AST cleanup pass):
```bash
google-java-format --aosp --max-line-length=120 --cleanup=false --replace $(git ls-files '*.java')
```
#### Configuring `prince-of-space` (Gradle, CLI, and Java API)
Because `prince-of-space` is built on JavaParser rather than internal `jdk.compiler` APIs, it runs on any standard JVM classpath without `--add-exports` flags.
You can run its standalone CLI JAR or embed `io.github.agustafson.princeofspace:prince-of-space-core:2.3.1` directly in Java.
When using it on Java 21 or Java 25 codebases, make sure to override `javaLanguageLevel` (which defaults to Java 17):
```java
import io.princeofspace.Formatter;
import io.princeofspace.model.FormatterConfig;
import io.princeofspace.model.IndentStyle;
import io.princeofspace.model.JavaLanguageLevel;
import io.princeofspace.model.WrapStyle;
FormatterConfig config = FormatterConfig.builder()
.indentStyle(IndentStyle.SPACES)
.indentSize(4)
.lineLength(120)
// BALANCED (1-per-line when wrapped), WIDE (bin-packed), or NARROW
.wrapStyle(WrapStyle.BALANCED)
// Put closing ')' on its own line (true) or keep it inline (false)
.closingParenOnNewLine(true)
.trailingCommas(false)
// Override default Java 17 level for Java 21-25 syntax support
.javaLanguageLevel(JavaLanguageLevel.of(25))
.build();
Formatter formatter = new Formatter(config);
String formatted = formatter.format(sourceCode);
```
If you prefer traditional Java parameter wrapping in `prince-of-space`, switching `.wrapStyle(WrapStyle.WIDE)` and `.closingParenOnNewLine(false)` brings its method signature layout much closer to Palantir and Open Java Format.
#### Configuring and Running `Netflix/jfmt` (CLI, `ToolProvider`, and Java API)
`Netflix/jfmt` is published on Maven Central as `com.netflix:com.netflix.tools.jfmt:0.9.0` (compiled for **JDK 25+**).
You can either install Netflix's [`ja`-enabled JDK toolchain](https://github.com/Netflix/ja#installation) (which bundles the `jfmt` launcher with all required `--add-exports` flags preconfigured) or run the standalone modular JAR directly on any standard JDK 25+ runtime:
```bash
# Option A: Using the jfmt launcher from a ja-enabled JDK 25
# Format files in place (pass -cp / -p so ImportNormalizer can resolve third-party types and expand wildcards)
jfmt -cp "lib/*" $(git ls-files '*.java')
# Check formatting in CI (exits with code 1 if any file is unformatted)
jfmt --check -cp "lib/*" $(git ls-files '*.java')
# Format from stdin to stdout (skips ImportNormalizer attribution)
jfmt - < src/main/java/demo/App.java
# Option B: Running the standalone JAR on any standard JDK 25+
java \
--add-exports=jdk.compiler/com.sun.tools.javac.api=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.code=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.file=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.model=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.parser=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.tree=ALL-UNNAMED \
--add-exports=jdk.compiler/com.sun.tools.javac.util=ALL-UNNAMED \
-jar com.netflix.tools.jfmt-0.9.0.jar -cp "lib/*" $(git ls-files '*.java')
```
In Java 25 code (with the 7 `jdk.compiler` `--add-exports` flags below), you can invoke `JfmtFormatter` for in-memory formatting, or `JfmtToolProvider` (which implements `java.util.spi.ToolProvider` with tool name `"jfmt"`) to run the full CLI pipeline including `ImportNormalizer` wildcard expansion and qualified-name shortening:
```java
import com.netflix.tools.jfmt.JfmtFormatter;
import com.netflix.tools.jfmt.JfmtToolProvider;
import java.io.PrintWriter;
// 1. In-memory source formatting (4-group import sorting + AST formatting, 8-pass convergence check):
var jfmt = new JfmtFormatter();
String formatted = jfmt.formatSource(sourceCode);
// 2. Full CLI + javac ImportNormalizer pipeline (expands import pkg.* and shortens pkg.Type):
// Note: On the classpath, instantiate JfmtToolProvider directly (with --add-exports=...=ALL-UNNAMED).
// If you load the JAR on --module-path and use ToolProvider.findFirst("jfmt"), target the named module
// in your exports instead (--add-exports=jdk.compiler/com.sun.tools.javac.*=com.netflix.tools.jfmt).
var tool = new JfmtToolProvider();
int exitCode = tool.run(
new PrintWriter(System.out, true),
new PrintWriter(System.err, true),
"-cp", classPath,
"src/main/java/demo/App.java");
```
#### Programmatic Java API and Required `--add-exports` Flags
Finally, if you invoke `google-java-format`, `palantir-java-format`, `open-java-format`, or `Netflix/jfmt` programmatically on the JVM (or run Spotless in-process on Gradle/Maven), you must pass the `jdk.compiler` module exports to your JVM (`org.gradle.jvmargs`, `.mvn/jvm.config`, or `maven-surefire-plugin`):
```text
--add-exports=jdk.compiler/com.sun.tools.javac.api=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.code=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.file=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.main=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.model=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.parser=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.tree=ALL-UNNAMED
--add-exports=jdk.compiler/com.sun.tools.javac.util=ALL-UNNAMED
--add-opens=jdk.compiler/com.sun.tools.javac.code=ALL-UNNAMED
--add-opens=jdk.compiler/com.sun.tools.javac.comp=ALL-UNNAMED
--add-opens=jdk.compiler/com.sun.tools.javac.parser=ALL-UNNAMED
```
With those flags in place, calling `open-java-format` (or `palantir-java-format`) from Java takes just a few lines:
```java
import com.palantir.javaformat.java.Formatter;
import com.palantir.javaformat.java.JavaFormatterOptions;
var options = JavaFormatterOptions.builder()
// Use Style.OJF in open-java-format, or Style.PALANTIR (supported by both)
.style(JavaFormatterOptions.Style.PALANTIR)
.formatJavadoc(true)
.build();
Formatter formatter = Formatter.createFormatter(options);
String formatted = formatter.formatSourceAndFixImports(sourceCode);
```
## Wrap-up
If you are happy with Google's 2-space, 100-column style, [google-java-format](https://github.com/google/google-java-format) `2.0.0` is a very welcome upgrade that finally fixes single-argument block lambdas and adds useful AST cleanups.
If you need a formatter library that embeds cleanly into a tool without `--add-exports` JVM flags, [prince-of-space](https://github.com/agustafson/prince-of-space) is worth keeping an eye on once its annotation duplication bug ([Issue #147](https://github.com/agustafson/prince-of-space/issues/147)) is fixed.
And if you are already on JDK 25 and intrigued by complexity-based structural line wrapping, column-aligned streams, and compiler-backed wildcard import expansion, [Netflix/jfmt](https://github.com/Netflix/jfmt) is a fascinating experiment to watch once its `{ /* ... */ }` non-convergence bug is resolved.
For my own Java projects, however, **[open-java-format](https://openjavaformat.dev/)** ([GitHub](https://github.com/openjavaformat/open-java-format)) hits the sweet spot: it gives me the readable 4-space, 120-column layout and inline lambda style of `palantir-java-format`, fixes the annoying JBang, `$NON-NLS$`, import, and string-wrapping bugs, and ships fast native binaries that make both human code reviews and AI agent diffs clean and predictable.
Give the [Open Java Format Playground](https://openjavaformat.dev/playground/) a spin on one of your own classes, and let me know which Java formatter you use in your projects!
## Addendum: Records, Text Blocks, and Pattern-Matching Switches
After sharing this post on social media, someone asked a great follow-up question: *of the five formatters, which ones handle recent Java features (like records, text blocks, and `switch` patterns) properly?*
Because `google-java-format` (`2.0.0`), `palantir-java-format` (`2.103.0`), `open-java-format` (`21.0.2`), and `Netflix/jfmt` (`0.9.0`) all parse code using the JDK's own `jdk.compiler` (`javac`) parser under the hood, all four support Java 21 to 25 syntax out of the box when run on JDK 25 (or via the standalone GraalVM native binaries for Google, Palantir, and Open Java Format).
However, they format several modern constructs quite differently, while `prince-of-space` (`2.3.1`, which relies on JavaParser) hits a few rough edges:
### 1. Switch Expressions and Pattern Matching (`when` Guards & Deconstruction)
When returning a pattern-matching `switch` expression directly (`return switch (shape) { ... }`), all five formatters keep record deconstruction patterns and `when` guards on clean single lines when they fit:
```java
return switch (shape) {
case Shape.Circle(var r) when r > 100.0 -> "large circle: " + r;
case Shape.Circle(var r) -> "circle: " + r;
case Shape.Rectangle(var w, var h) when w == h -> "square: " + w;
case Shape.Rectangle(var w, var h) -> "rect: " + w + "x" + h;
};
```
Where they diverge is **assigning a `switch` expression to a variable** (`String label = switch (code) { ... };`):
- **`open-java-format`, `palantir-java-format`, and `Netflix/jfmt`** keep the assignment and `switch` header on a single line, so the `case` arms indent just one level inside the method:
```java
// open-java-format 21.0.2, palantir-java-format 2.103.0 & Netflix/jfmt 0.9.0
String label = switch (code) {
case 1 -> "one";
case 2 -> "two";
default -> "other";
};
```
- **`google-java-format` (`2.0.0`)** forces a line break after `=` and indents the entire `switch` block one level deeper:
```java
// google-java-format 2.0.0
String label =
switch (code) {
case 1 -> "one";
case 2 -> "two";
default -> "other";
};
```
- **`prince-of-space` (`2.3.1`)** has three caveats on modern `switch` expressions:
1. Its default configuration (`FormatterConfig.defaults()`) targets **Java 17**, throwing a parse error on Java 21 `when` guards, record patterns, or Java 25 flexible constructor bodies unless you explicitly configure `JavaLanguageLevel.of(21)` or `of(25)`.
2. Even with `JavaLanguageLevel.of(25)`, JavaParser currently fails to parse combined type patterns with unnamed variables such as `case Integer _, Long _ ->` ([Issue #109](https://github.com/agustafson/prince-of-space/issues/109)).
3. On variable assignments, `prince-of-space` breaks after `=` and indents `switch (code) {` by **16 spaces**, while indenting the inner `case` arms by only **12 spaces** (leaving the `case` arms outdented to the left of their own `switch` header):
```java
// prince-of-space 2.3.1 (switch header indented deeper than its case arms)
String label =
switch (code) {
case 1 -> "one";
case 2 -> "two";
default -> "other";
};
```
### 2. Text Blocks (`""" ... """`) and `.formatted(...)`
All five formatters preserve the relative indentation inside a text block (since modifying interior indentation would alter the runtime `String` value).
The main visual difference appears when chaining `.formatted(...)` (or `.stripIndent()`, `.translateEscapes()`, etc.) onto the closing `"""` delimiter:
- **`open-java-format` and `palantir-java-format`** keep `.formatted(...)` inline on the closing `"""`:
```java
// open-java-format 21.0.2 & palantir-java-format 2.103.0
public String report(Shape s) {
return """
Shape Report
------------
Description: %s
""".formatted(describe(s));
}
```
- **`google-java-format` (`2.0.0`) and `Netflix/jfmt` (`0.9.0`)** break `.formatted(...)` onto a new line below `"""` (with 2-space/4-space indentation in `google-java-format` vs. 4-space/8-space indentation in `Netflix/jfmt`):
```java
// Netflix/jfmt 0.9.0 (google-java-format 2.0.0 is similar with 2-space indent)
public String report(Shape s) {
return """
Shape Report
------------
Description: %s
"""
.formatted(describe(s));
}
```
- **`prince-of-space` (`2.3.1`)** keeps `.formatted(` on the closing `"""` when a single argument is passed, but wraps the argument and closing `);` across three lines:
```java
// prince-of-space 2.3.1
public String report(Shape s) {
return """
Shape Report
------------
Description: %s
""".formatted(
describe(s)
);
}
```
### 3. Records and Compact Constructors
All five formatters handle short single-line records (`record Rectangle(double width, double height) implements Shape {}`), nested records inside `sealed` interfaces, and compact constructors (`public Circle { ... }`) cleanly.
When a record declaration has enough components to wrap across multiple lines (or 4+ components in `Netflix/jfmt`), `google-java-format`, `palantir-java-format`, `open-java-format`, and `Netflix/jfmt` keep the closing `) {` inline after the last component (with `Netflix/jfmt` using a single continuation break before the 4th component for 4 to 6 simple components, column-aligned under `(` when `(` sits at or before column 24, and one component per line for 7+ simple components or complex component types).
Meanwhile, `prince-of-space` places `) {` on its own line, and both `prince-of-space` and `Netflix/jfmt` automatically insert `{ ... }` braces around any braceless `if` validation inside the compact constructor:
```java
// open-java-format 21.0.2 & palantir-java-format 2.103.0
record DetailedProfile(
String firstName,
String lastName,
String email,
String phone,
String address,
String city,
String country,
int age) {
DetailedProfile {
if (age < 0) throw new IllegalArgumentException("Age must be non-negative: " + age);
}
}
```
In short, if your codebase leans heavily on Java 21 to 25 features like records, pattern-matching `switch` expressions, text blocks, unnamed variables (`_`), JEP 467 `///` Markdown doc comments, or JEP 513 flexible constructor bodies, **`open-java-format`** and **`palantir-java-format`** produce the cleanest, most idiomatic layout out of the box.
# Monday Morning SDK Maintenance with Antigravity Scheduled Automations
Maintaining an unofficial SDK (or two) means playing a constant game of catch-up with upstream APIs.
Over the past few months, I have been maintaining two Java libraries: the [Gemini Interactions API Java SDK]({{< ref "/posts/2026/06/24/gemini-interactions-api-now-ga-exploring-the-release-candidate-of-my-java-sdk.md" >}}) and the [unofficial Antigravity SDK for Java]({{< ref "/posts/2026/07/31/the-unofficial-antigravity-sdk-for-java.md" >}}).
Both upstream targets move fast.
The Gemini Interactions API updates its public OpenAPI specification (`interactions.openapi.json`) whenever new agent capabilities, voice synthesis options, or webhook parameters land.
Meanwhile, the official Antigravity Python SDK publishes new wheels to PyPI containing updated native Go `localharness` binaries, compiled Protobuf descriptors, and new Python classes.
Instead of manually checking both upstream sources every week, I configured two scheduled automations in [Google Antigravity](https://antigravity.google/).
Every Monday morning at 9:00 AM, Antigravity wakes up, spins up two fresh agent sessions in the background, audits the upstream changes against my local repositories, and prepares a complete implementation plan waiting for my review when I sit down with my coffee.
This morning (Monday, November 2), both automations found upstream changes, drafted their plans, implemented the code and unit tests after my review, and allowed me to release new versions of both SDKs to Maven Central before 10:00 AM.
> [!NOTE]
> Both releases are live on GitHub and Maven Central:
> - [Gemini Interactions API Java SDK `v2.1.1`](https://github.com/glaforge/gemini-interactions-api-sdk) (`io.github.glaforge:gemini-interactions-api-sdk:2.1.1`)
> - [Antigravity SDK for Java `v0.3.3`](https://github.com/glaforge/antigravity-java-sdk) (`io.github.glaforge.antigravity:antigravity-sdk-wrapper:0.3.3`)
## How Antigravity Scheduled Automations Work
Antigravity includes a customization system built around rules (`GEMINI.md`, `AGENTS.md`), on-demand skills (`SKILL.md`), MCP servers, plugins, and background sidecars.
A scheduled automation is a built-in `schedule` sidecar that runs on a standard 5-field cron expression and invokes `agentapi new-conversation` to start a new agent turn on each trigger.
Because each scheduled run starts a brand-new conversation with no memory of previous weeks, my setup splits the responsibility into two layers:
1. A lightweight `sidecar.json` automation file in `~/.gemini/config/sidecars//sidecar.json` that defines the cron schedule (`0 9 * * 1` for Monday at 9:00 AM) and a short trigger prompt.
2. Detailed, repository-specific instructions checked into git (`AGENTS.md`, `UPDATING_SDK.md`, and helper scripts like `sync-harness.sh`) that tell the agent how the project is structured and how to audit upstream changes.
Keeping the detailed synchronization steps inside `AGENTS.md` in each git repository keeps the cron prompt short and ensures that any manual conversation in that workspace benefits from the exact same instructions.
## Setting Up the Two Monday Morning Automations
You can create a scheduled automation interactively by typing `/automation` in Antigravity, or visually from Antigravity 2.0's **Automations** panel in the left sidebar (clicking **Create with Prompt** or **+ New**).
The built-in `automation` skill walks you through choosing a cadence (hourly, daily, weekly, or custom cron), picking the day and time, writing the prompt, and running a test turn to record the required file and URL permissions.
Under the hood, Antigravity writes a `sidecar.json` file for each automation.
Here are the two configurations I use.
### 1. Checking the Gemini Interactions OpenAPI Spec
The first automation lives in `~/.gemini/config/sidecars/check-remote-api/sidecar.json`:
```json
{
"builtin": "schedule",
"restart_policy": "always",
"args": [
"0 9 * * 1",
"agentapi",
"new-conversation",
"--",
"Check if there's an update on the remote OpenAPI JSON file, and prepare an implementation plan with the needed changes"
],
"display_name": "Interactions API > Check remote API"
}
```
When this automation runs in the `gemini-interactions-api-sdk` workspace, the agent automatically reads the repository's `AGENTS.md` file, which points it to `UPDATING_SDK.md`.
That document gives the agent its step-by-step runbook:
1. Fetch the official OpenAPI specification from `https://ai.google.dev/static/api/interactions.openapi.json`.
2. Diff it against the local `openapi.json` copy stored at the root of the repository:
```bash
curl -s https://ai.google.dev/static/api/interactions.openapi.json > remote_openapi.json
diff -u openapi.json remote_openapi.json
```
3. Analyze any added, modified, or removed schemas, endpoints, query parameters, and Server-Sent Events (SSE) delta types.
4. Keep backward compatibility in mind: when the upstream OpenAPI spec removes an experimental field or enum constant, mark the corresponding Java record or enum value as `@Deprecated` rather than deleting it and breaking existing callers.
5. Plan the updates across the Java 21 model records, builders, `GeminiInteractionsClient`, unit tests, `README.md`, and the bundled Agent Skill (`skills/gemini-interactions-java-api/SKILL.md`).
### 2. Checking the Antigravity Python SDK and Native Go Harness
The second automation is defined in `~/.gemini/config/sidecars/check-new-version/sidecar.json`:
```json
{
"builtin": "schedule",
"restart_policy": "always",
"args": [
"0 9 * * 1",
"agentapi",
"new-conversation",
"--",
"Check if there's a new version of the Antigravity Python SDK wheel, and embedded Go localharness. \nYou can also check the official website changelog to see if they mention new versions with detailed release notes here: https://antigravity.google/docs/changelog?tab=sdk\nIf there's an update, prepare an implementation plan detailing the needed changes."
],
"display_name": "AGY Java SDK > Check new version"
}
```
Synchronizing the Antigravity Java SDK is more involved because there is no single OpenAPI file to diff.
As I explained when [introducing the Antigravity SDK for Java]({{< ref "/posts/2026/07/31/the-unofficial-antigravity-sdk-for-java.md" >}}), the official Python SDK wraps a native Go binary called `localharness` and communicates with it over standard input/output and WebSockets using Protobuf messages.
To make this repeatable for the agent, I documented a 6-step upstream synchronization workflow in the repository's `AGENTS.md`:
| Step | What the Agent Does |
| :--- | :--- |
| **1. Check PyPI & Sync Binaries** | Queries `https://pypi.org/pypi/google-antigravity/json` via `./sync-harness.sh`, compares the upstream version against `antigravity-sdk-harness/.../.version`, downloads the 6 platform wheels (`linux-x86_64`, `linux-aarch64`, `osx-aarch64`, `osx-x86_64`, `windows-x86_64`, `windows-aarch64`), and unpacks the Python source into `/tmp/antigravity_upstream/`. |
| **2. Extract Compiled Protobuf Descriptors** | Decompiles the binary `FileDescriptorProto` directly from `localharness_pb2.py` and `content_pb2.py` in Python so it never has to guess wire field names (Go's `localharness` rejects unknown JSON fields immediately). |
| **3. Audit Python Source & Tests** | Diffs the unpacked Python package (`types.py`, `connection_config.py`, `hooks/policy.py`, `workflows.py`, and `*_test.py`) against the previous version, cross-referencing the public changelog at `antigravity.google/docs/changelog?tab=sdk`. |
| **4. Update Code & Parity Tests** | Updates `localharness.proto`, Java builders, and records, and creates a dedicated `FeatureParityTest.java` unit test class covering every new capability. |
| **5. Verify Wire Compatibility** | Runs fast unit tests (`./mvnw test`), formats code (`./mvnw spotless:apply`), and runs a live smoke test against the new `localharness` binary. |
| **6. Sync Docs & Agent Skill** | Updates `README.md` and `skills/antigravity-sdk-java/SKILL.md` so coding agents using the Java SDK know about the new APIs. |
For step 2, having this tiny Python snippet right inside `AGENTS.md` saves the agent from ever guessing a Protobuf field name:
```python
import google.protobuf.descriptor_pb2 as d_pb2
from google.antigravity.proto import localharness_pb2
proto = d_pb2.FileDescriptorProto()
localharness_pb2.DESCRIPTOR.CopyToProto(proto)
print(proto)
```
### Enabling the Automations and Project Permissions
Once the `sidecar.json` files are created, you enable them in the Antigravity Automations dashboard (`sidecar://dashboard`) and bind each automation to its target project workspace.
Because scheduled automations run unattended at 9:00 AM, they only have access to the permissions granted to their project (plus global permissions in `~/.gemini/config/config.json`).
Any unapproved shell command or external domain fetch is automatically denied during a background run.
Running a test turn when setting up the automation lets you approve `read_url(ai.google.dev)`, `read_url(antigravity.google)`, `curl -s https://pypi.org/pypi/google-antigravity/json`, and `./mvnw` once, so the Monday morning check can complete its analysis without getting stuck on a permission prompt.
Notice also what the automation prompt asks the agent to do: *"prepare an implementation plan detailing the needed changes"*.
I intentionally stop the unattended run at the planning stage.
I want the agent to do all the research, diffing, and design work on its own, and then pause with an implementation plan artifact so I can review the proposed changes before it touches the code or triggers a release.
## What Happened This Morning: Two Automated Audits, Two Releases
When I opened Antigravity this morning shortly after 9:10 AM, both Monday automations had just finished running and had produced detailed implementation plans.
### 1. Gemini Interactions API Java SDK `v2.1.1`
In the Gemini Interactions SDK workspace, the agent spotted that the remote `interactions.openapi.json` specification had changed across 22 schemas (with 4 newly added schemas and 29 legacy schemas removed) and prepared the implementation plan.
I reviewed the plan, clicked **Proceed**, and let the agent update 21 files, add a 314-line unit test suite (`OpenApiUpdateNov02Test.java`), verify that `./mvnw test` and `./mvnw javadoc:javadoc` passed without warnings, and update both `README.md` and `SKILL.md`.
{{< details summary="Click to see what changed in Gemini Interactions API Java SDK v2.1.1" >}}
- Interaction continuation and metadata: A new `REQUIRES_CONTINUATION` status value on `Interaction.Status` (used alongside `continuationToken` when resuming paused interactions), plus per-interaction `webhookConfig`, custom `labels` (`Map`), `maxTotalTokens`, and `initialInputTokens` in `Usage`.
- Model environments: `ModelInteractionParams` now supports attaching a `BaseEnvironment` or `environmentId` directly, matching `CreateModelInteractionParams` in the spec.
- Speech configuration and voice remixing: `GenerationConfig` renamed `speech_config` to `structured_speech_config` (which we mapped with `@JsonProperty("structured_speech_config")` and `@JsonAlias("speech_config")` so existing JSON payloads and builder methods keep working), and `PromptedVoice` added a `base_voice` property to remix an existing voice from a natural-language prompt:
```java
Voice remixedVoice = client.createVoice(Voice.builder()
.model(ModelOption.GEMINI_3_8_FLASH_TTS)
.displayName("Faster Astronomer")
.prompted("Speak at a brisk, energetic pace", astronomer.id())
.build());
```
- Client query parameter overloads: New overloads on `GeminiInteractionsClient` for `createAgent(agent, parent)`, `listTriggerExecutions(triggerId, pageSize, pageToken, filter)`, and `createWebhook(webhook, webhookId)`.
- Non-breaking deprecations: Rather than deleting the 29 removed schemas (such as legacy RAG/Retrieval steps and `CodeMenderAgentConfig`), the agent marked them with `@Deprecated` so existing users upgrading to `v2.1.1` will not hit compilation errors.
{{< /details >}}
### 2. Antigravity SDK for Java `v0.3.3` (Upstream `v0.1.23` Parity)
In parallel, the second automation detected that the upstream `google-antigravity` package on PyPI had moved from `0.1.22` to `0.1.23`.
Once I approved its 6-phase upgrade plan, the agent synchronized the native Go binaries, updated 21 files, wrote 369 lines of parity tests in `FeatureParity0123Test.java`, ran Spotless and the test suite, and updated the documentation and skill files.
{{< details summary="Click to see what changed in Antigravity SDK for Java v0.3.3" >}}
- Native Go `localharness` `v0.1.23`: Updated the binaries across all 6 OS/architecture slices and added the new Protobuf fields in `localharness.proto` (`SectionHeaderFormat`, `CustomSystemInstructions.Part.title`, `ToolOutputTruncation`, `SkillsConfig` options, and `BASH` in `CodeExecutionCallArguments.Language`).
- Workflow `callTool`, multi-turn `WorkflowAgent`, and runtime `args`: You can now invoke parent agent tools directly inside workflows (`callTool` / `callToolExpr`), define persistent multi-turn subagents inside a workflow (`defineAgent` and `callAgent`), and pass a `Map` of runtime arguments to `agent.beta().runWorkflow(...)`:
```java
AgentConfig config = AgentConfig.builder()
.customInstructions("Enforce strict null-safety and immutable records.", "CodingStandards")
.capabilities(CapabilitiesConfig.builder()
.enableSubagents(true)
.enableRunWorkflow(true)
.build())
.build();
WorkflowDefinition workflow = Workflows.builder("pr_review_workflow")
.description("Read target file and run multi-turn review")
.phase("Read")
.callToolExpr("file_content", "view_file", Map.of("Path", "args.get('target', 'README.md')"))
.phase("Review")
.defineAgent("reviewer", "You are a principal Java reviewer.", "Reviewer", "self", "inherit")
.callAgent("initial_pass", "reviewer", "Summarize key risks in the file", String.class)
.callAgent("final_verdict", "reviewer", "Provide final pass/fail verdict", String.class)
.logExpr("initial_pass", "final_verdict")
.build();
try (Agent agent = new Agent(config)) {
WorkflowResult result = agent.beta()
.runWorkflow(
workflow,
Map.of("target", "pom.xml"),
progress -> System.out.println("Progress: " + progress.output()))
.get(120, TimeUnit.SECONDS);
System.out.println("Workflow result:\n" + result.output());
}
```
- Titled custom system instructions: `CustomSystemInstructions.of(text, title)` and `.customInstructions(text, title)` wrap custom instructions in a named section header tag instead of a generic `` block.
- JSON Schema `readOnly` / `writeOnly` and utilities: Added `readOnly` and `writeOnly` support to `@Param` and `SchemaGenerator`, canonical path normalization on `ToolCall.canonicalPath()`, `~` home directory expansion on `AgentInput.Media.fromFile(...)`, and `DiffFormatter.formatDiffBlocks(...)` for formatting `edit_file` diff blocks into unified diffs.
{{< /details >}}
### 3. Human Review and Manual Release
By 9:50 AM, both workspaces had clean git diffs, passing test suites, and updated documentation.
I did a final review of the commits, pushed them to `main`, and manually triggered the GitHub Actions release workflows (which use [JReleaser](https://jreleaser.org/) to sign and publish the artifacts to Maven Central and create the GitHub releases).
Keeping a human gate at two points in the loop (approving the implementation plan before code generation, and manually triggering the Maven Central release after inspecting the diff) gives me the best balance between speed and control.
What used to take several hours of tedious spec diffing and Protobuf reverse-engineering now takes about twenty minutes of reviewing plans and diffs on Monday morning.
## Wrap-up
If you maintain an SDK, an API client, or an integration that tracks an external specification or upstream repository, pairing a cron-triggered Antigravity automation (`sidecar.json`) with a well-structured `AGENTS.md` runbook is a very practical workflow to set up.
You can start small by typing `/automation` in Antigravity, pointing an agent at your upstream changelog or OpenAPI spec every Monday morning, and letting it hand you an implementation plan before you even finish your first cup of coffee.
# Agent eXperience (AX) in practice: Serving this Hugo blog as Markdown
Back in March 2025, I added [`llms.txt` and `llms-full.txt` support to this blog]({{< ref "/posts/2025/03/03/llms-txt-to-help-llms-grok-your-content.md" >}}).
The goal was to give Large Language Models a structured index of all my articles, plus a single consolidated file (`llms-full.txt`) that I could drop into Gemini's large context window to ask questions across everything I had ever written.
Since then, the way developers and AI tools interact with web content has evolved quite a bit.
Instead of manually uploading a 700k-token file into a chat prompt, we now rely on autonomous coding agents (like [Antigravity](https://antigravity.google/), Claude Code, GitHub Copilot, Cursor, or OpenCode) that browse the web and fetch individual documentation pages or blog posts on the fly.
Today, I took another step to make this blog friendlier to those agents: every article now has a clean Markdown twin (`.md`), linked from the HTML header and from `llms.txt`.
> [!NOTE]
> You can view the Markdown version of this very article at [agent-experience-in-practice-serving-this-hugo-blog-as-markdown.md](/posts/2026/10/30/agent-experience-in-practice-serving-this-hugo-blog-as-markdown.md), or inspect the updated site index at [llms.txt](/llms.txt).
## The Rise of Agent eXperience (AX)
Before looking at the Hugo configuration, it is worth stepping back to look at the broader shift behind this change: **Agent eXperience (AX)**.
In early 2025, Netlify CEO Mathias Biilmann coined the term *Agent Experience* to describe the holistic experience AI agents have as users of a product, platform, or website.
In an interview with Richard MacManus on The New Stack ([Beyond DX: Developers Must Now Learn Agent Experience (AX)](https://thenewstack.io/beyond-dx-developers-must-now-learn-agent-experience-ax/)), Biilmann noted that over a thousand sites were already being deployed to Netlify every day directly from ChatGPT and coding agents, requiring completely different authentication, handoff, and documentation flows than those built for humans alone.
Several recent articles have explored what AX means in practice for software teams and content creators:
- [Agents: The new, New Kingmakers](https://redmonk.com/sogrady/2026/09/16/new-new-kingmakers/) by Stephen O'Grady at RedMonk revisits his classic *New Kingmakers* thesis. A decade ago, developers became the decision-makers choosing which languages, libraries, and databases succeeded. Today, coding agents increasingly make those technology choices directly from a prompt (choosing frameworks, dependencies, and APIs on the developer's behalf).
- [What's the Difference between Generative Engine Optimization (GEO) & Agent Experience (AX)?](https://redmonk.com/kholterhoff/2026/08/24/ax-v-geo/) by Kate Holterhoff (also at RedMonk) draws a helpful boundary between marketing-driven GEO and engineering-driven AX: *"GEO gets you mentioned. AX determines what happens next."* Getting cited in an AI summary is one thing; making sure an agent can actually read your docs or operate your tool without failing is another.
- [Agent experience is the new developer experience](https://www.builder.io/blog/agent-experience) by Alice Moore at Builder.io looks at AX inside codebases. Because coding agents are stateless, they need minimal, transparent context and deterministic verification loops rather than bloated prompts.
- [Stop Getting Good at Protocols, Get Good at Agent Experience](https://www.oreilly.com/radar/stop-getting-good-at-protocols-get-good-at-agent-experience/) by Sean Roberts on O'Reilly Radar warns teams against chasing the "protocol of the month" (whether MCP, A2A, or skills) as a strategy in itself, instead of focusing on how reliably agents can discover, understand, and act on your services.
### AX in Developer Relations
This shift hits particularly close to home for those of us working in Developer Relations.
My friend [Patrick Chanezon](https://blog.chanezon.com/), who leads Developer Relations at Microsoft, wrote a thoughtful piece last November on [Reinventing Developer Relations in the age of AI Agents](https://blog.chanezon.com/2025/11/07/devrel-evolution-with-ai-agents.html).
In it, Patrick outlined three dimensions for the evolution of DevRel:
1. Helping developers transition from individual contributors to "managers of agents".
2. Transforming our own DevRel workflows with AI.
3. Treating AI agents as a primary user persona of our developer services and documentation, which means investing in Agent Experience (AX).
As Patrick pointed out, you cannot improve what you do not measure.
Just last week, he followed up with [Measuring Agent Experience: open sourcing the platform we use, Project Scope, and an AX practitioner handbook](https://blog.chanezon.com/2026/10/19/ax-handbook-and-project-scope.html), announcing the open-sourcing of Microsoft's *AX Practitioner Playbook* and *Scope*, a Kubernetes-based evaluation harness to benchmark how coding agents perform multi-turn tasks across different harnesses, models, skills, and MCP servers.
## Why `llms.txt` Alone Wasn't Enough
In her RedMonk article on AX vs. GEO, Kate Holterhoff pointed out an uncomfortable truth about `llms.txt`: while it was proposed as a discovery standard, web server traffic analysis (such as the study by Evil Martians) showed that very few AI agents automatically probe `/llms.txt` on their own when asked to read a page.
In practice, when a developer pastes a blog post URL into Claude Code, Cursor, or [Antigravity CLI](https://antigravity.google/product/antigravity-cli/) (or when an agent follows a link from a search tool), the agent fetches that specific URL directly.
Until today, my `/llms.txt` file also linked to the HTML URLs of my posts.
When an agent fetched one of those URLs, it received the full HTML document: header menus, social links, sidebar widgets, lightbox markup, and tens of kilobytes of inline syntax-highlighting `` tags generated by Hugo.
Two resources inspired me to fix this:
- [acceptmarkdown.com](https://acceptmarkdown.com/), a guide and testing tool created by Ben Word that tracks which AI agents send `Accept: text/markdown` headers (currently supported by Claude Code, GitHub Copilot Chat and CLI, Cursor, OpenCode, and OpenClaw) or follow `` tags (used by OpenAI's Codex CLI).
- Marko Denic's article, [How to Serve Markdown to AI Agents (and Why)](https://markodenic.com/serve-markdown-to-ai-agents/), which explains how to publish a `.md` twin for every page and configure HTTP content negotiation.
How much difference does serving clean Markdown make on this blog?
Because Hugo's syntax highlighter wraps every token of every code snippet in `` tags, the HTML pages are much heavier than the underlying prose and code.
Here is the raw size comparison on five recent articles from this blog:
| Article | HTML (`index.html`) | Markdown (`.md`) | Reduction |
| :--- | ---: | ---: | ---: |
| [The eMudhra CA Compromise]({{< ref "/posts/2026/10/21/the-emudhra-ca-compromise-why-your-jvm-is-vulnerable-and-how-to-fix-it.md" >}}) | 69.1 KB | 23.5 KB | **2.9x** |
| [Crafting a Devoxx Schedule with Gemini]({{< ref "/posts/2026/09/28/crafting-a-devoxx-schedule-with-gemini-langchain4j-and-micronaut.md" >}}) | 57.0 KB | 16.8 KB | **3.4x** |
| [Gemini 3.8 Flash TTS with Java]({{< ref "/posts/2026/09/24/gemini-3-8-flash-tts-and-custom-voices-with-the-interactions-java-sdk.md" >}}) | 34.9 KB | 8.9 KB | **3.9x** |
| [The Unofficial Antigravity SDK for Java]({{< ref "/posts/2026/07/31/the-unofficial-antigravity-sdk-for-java.md" >}}) | 49.8 KB | 14.3 KB | **3.5x** |
| [Sharing a Git-Backed Obsidian Vault]({{< ref "/posts/2026/09/13/sharing-a-git-backed-obsidian-vault-across-computers.md" >}}) | 16.6 KB | 6.8 KB | **2.4x** |
Beyond saving bytes and tokens, the agent gets clean fenced code blocks (` ```java `) instead of nested HTML spans, with zero navigation clutter.
> [!NOTE]
> **What about `noClasses = false` vs. `noClasses = true`?**
> On Mastodon, a reader suggested switching Hugo's syntax highlighter from `noClasses = true` (inline `style="color:..."` attributes) to `noClasses = false` with an external stylesheet (`hugo gen chromastyles --style=friendly`) so that agents falling back to `index.html` also get lighter markup.
> I tested this and made the switch! Interestingly, the total `index.html` file sizes barely changed (~1 KB difference). Why? Because with `noClasses = true`, Chroma only wraps tokens that actually have a color style; with `noClasses = false`, Chroma wraps *every single token* in `` tags, including punctuation (`;`), plain identifiers (`foo`), and even whitespace (``). While switching to CSS classes is cleaner for styling and dark mode, every line of code in HTML is still broken into dozens of `` tags, which is why the `.md` twin remains ~3x smaller and much easier for LLMs to tokenize.
## Generating Markdown Twins with Hugo
Since my blog content is already authored in Markdown with Hugo, and served via GitHub Pages, generating a clean `.md` twin at build time only took four small changes.
### 1. Enabling the `markDown` output format in `config.toml`
Hugo includes a built-in `markDown` output format with the `text/markdown` media type.
By default, Hugo outputs `/posts/YYYY/MM/DD/slug/index.md`.
I wanted the shorter `/posts/YYYY/MM/DD/slug.md` URL pattern (matching Marko Denic's setup).
In Hugo, you can achieve this without changing your existing HTML URLs by enabling `uglyURLs = true` globally while setting `noUgly = true` on `HTML` and `RSS`, and `noUgly = false` on `markDown`:
```toml
uglyURLs = true
[outputFormats.HTML]
noUgly = true
[outputFormats.RSS]
noUgly = true
[outputFormats.llms]
baseName = "llms"
mediaType = "text/plain"
isPlainText = true
noUgly = true
[outputFormats.llms-full]
baseName = "llms-full"
mediaType = "text/plain"
isPlainText = true
noUgly = true
[outputFormats.markDown]
mediaType = "text/markdown"
isPlainText = true
noUgly = false
[outputs]
home = ["HTML", "RSS", "llms", "llms-full"]
page = ["HTML", "markDown"]
```
### 2. Creating the Markdown template (`layouts/_default/single.md`)
Instead of copying the raw source file with its YAML frontmatter, I created a `single.md` template in my theme (`themes/glaforge-from-blank/layouts/_default/single.md`).
Following Marko Denic's recommendation, it starts with the article title, description, metadata (author, publication date, tags, and canonical URL), and then outputs the Markdown content while resolving Hugo's internal `{{}}` shortcodes into full URLs:
```go-html-template
# {{ .Title }}
{{- with .Description }}
> {{ . }}
{{- end }}
Author: [{{ .Site.Params.author.name | default .Site.Title }}]({{ .Site.BaseURL }}) | Published: {{ .Date.Format "2006-01-02" }}{{ if and (not .Lastmod.IsZero) (ne (.Lastmod.Format "2006-01-02") (.Date.Format "2006-01-02")) }} | Updated: {{ .Lastmod.Format "2006-01-02" }}{{ end }}{{ with .Params.tags }} | Topics: {{ delimit . ", " }}{{ end }} | Canonical: {{ if .Params.canonical }}{{ .Params.canonical }}{{ else }}{{ .Permalink }}{{ end }}
{{ $content := .RawContent -}}
{{- $content = $content | replaceRE `\{\{<\s*ref\s+"/"\s*>\}\}` .Site.BaseURL -}}
{{- $content = $content | replaceRE `\{\{<\s*ref\s+"/?([^"]+?)(\.md)?"\s*>\}\}` (printf "%s$1/" .Site.BaseURL) }}
{{ $content }}
```
### 3. Advertising the Markdown and `llms.txt` versions in ``
For agents that fetch the HTML page first and look for a machine-readable alternative (like OpenAI's Codex CLI), I added `` tags right below `` in `layouts/_default/baseof.html`, pointing to `llms.txt`, `llms-full.txt`, and the page's `.md` twin:
```go-html-template
{{ with .OutputFormats.Get "markDown" -}}
{{ printf `` .Rel .MediaType.Type .Permalink $.Title | safeHTML }}
{{- end }}
```
### 4. Pointing `llms.txt` directly to the `.md` files
Finally, I updated `layouts/_default/index.llms.txt` so that `/llms.txt` includes a short `## Programmatic access` guide for agents and links directly to the `.md` twin of each article rather than the HTML page:
```go-html-template
## Programmatic access
Agents and automated tools can access this blog's content in clean Markdown without HTML chrome:
- Fetch [llms.txt]({{ .Site.BaseURL }}llms.txt) for a structured index of all articles with direct links to their `.md` versions.
- Fetch [llms-full.txt]({{ .Site.BaseURL }}llms-full.txt) to ingest the entire blog corpus in a single Markdown document.
- Append `.md` to any article URL (or follow the `` tag in any page's HTML ``) to retrieve the raw Markdown twin of that article.
## All articles
{{ range .Site.RegularPages.GroupByDate "2006" }}
### {{ .Key }}
{{ range .Pages }}
{{- $url := .Permalink -}}
{{- with .OutputFormats.Get "markDown" -}}{{- $url = .Permalink -}}{{- end }}
- [{{- .Title -}}]({{- $url -}})
{{- end -}}
{{ end }}
```
## The Limitations of Static Hosting on GitHub Pages
While this static Hugo setup gets us a long way, hosting on GitHub Pages comes with a few HTTP-level limitations that are worth calling out.
First, the good news: when Hugo builds the `.md` files and deploys them via GitHub Actions, GitHub Pages serves them with the proper [RFC 7763](https://www.rfc-editor.org/rfc/rfc7763.html) MIME type and UTF-8 charset parameter out of the box:
```http
HTTP/2 200
server: GitHub.com
content-type: text/markdown; charset=utf-8
```
However, because GitHub Pages is a purely static file host with no custom server configuration or header rules, two pieces from [acceptmarkdown.com](https://acceptmarkdown.com/) and Marko Denic's post are not possible on GitHub Pages alone:
1. **No HTTP Content Negotiation (`Accept: text/markdown`) on canonical URLs**:
When an agent like Claude Code or Cursor requests `https://glaforge.dev/posts/2026/10/30/agent-experience-in-practice-serving-this-hugo-blog-as-markdown/` with `Accept: text/markdown`, GitHub Pages cannot dynamically rewrite that request to serve `agent-experience-in-practice-serving-this-hugo-blog-as-markdown.md`. It will still return `index.html` (`text/html`). To get the Markdown version, the agent (or user) either needs to follow the `` tag in ``, follow the link from `/llms.txt`, or append `.md` to the URL (stripping the trailing slash).
2. **No custom HTTP response headers (`Link`, `Vary`, `Cache-Control`)**:
GitHub Pages does not support `_headers` files. We cannot attach a `Link: <...>; rel="canonical"` HTTP response header to the `.md` files, nor set `Vary: Accept` or `Cache-Control: private`. Including the `Canonical:` URL at the top of the Markdown text helps agents identify the canonical source, even without the HTTP `Link` header.
> [!TIP]
> If you want full `Accept: text/markdown` content negotiation and custom HTTP headers in front of GitHub Pages, the easiest option is to put your domain behind **Cloudflare** (either using a small Cloudflare Worker to route `Accept: text/markdown` requests to the `.md` file and set the `Vary` and `Link` headers, or enabling Cloudflare's *Markdown for Agents* feature) or to host on a platform that supports header-based rewrites like Netlify or Vercel.
## Auditing the Blog with `anc.dev`
To see how the blog fared against an automated agent-readiness checker, I ran it through [anc.dev](https://anc.dev/) (which practices what it preaches by serving its own audit report as clean Markdown at [`https://anc.dev/score/glaforge.dev/md`](https://anc.dev/score/glaforge.dev/md)).
Out of the box, the audit verified `/robots.txt`, `/sitemap.xml`, `/llms.txt`, `/llms-full.txt`, resolvable `.md` links inside `llms.txt`, Schema.org JSON-LD metadata, and semantic HTML landmarks (``, ``, `