
Running Gemma 4 locally on Mac: Benchmarking Qxotic Jinfer, llama.cpp, MLX, and connecting Java 25 with LangChain4j
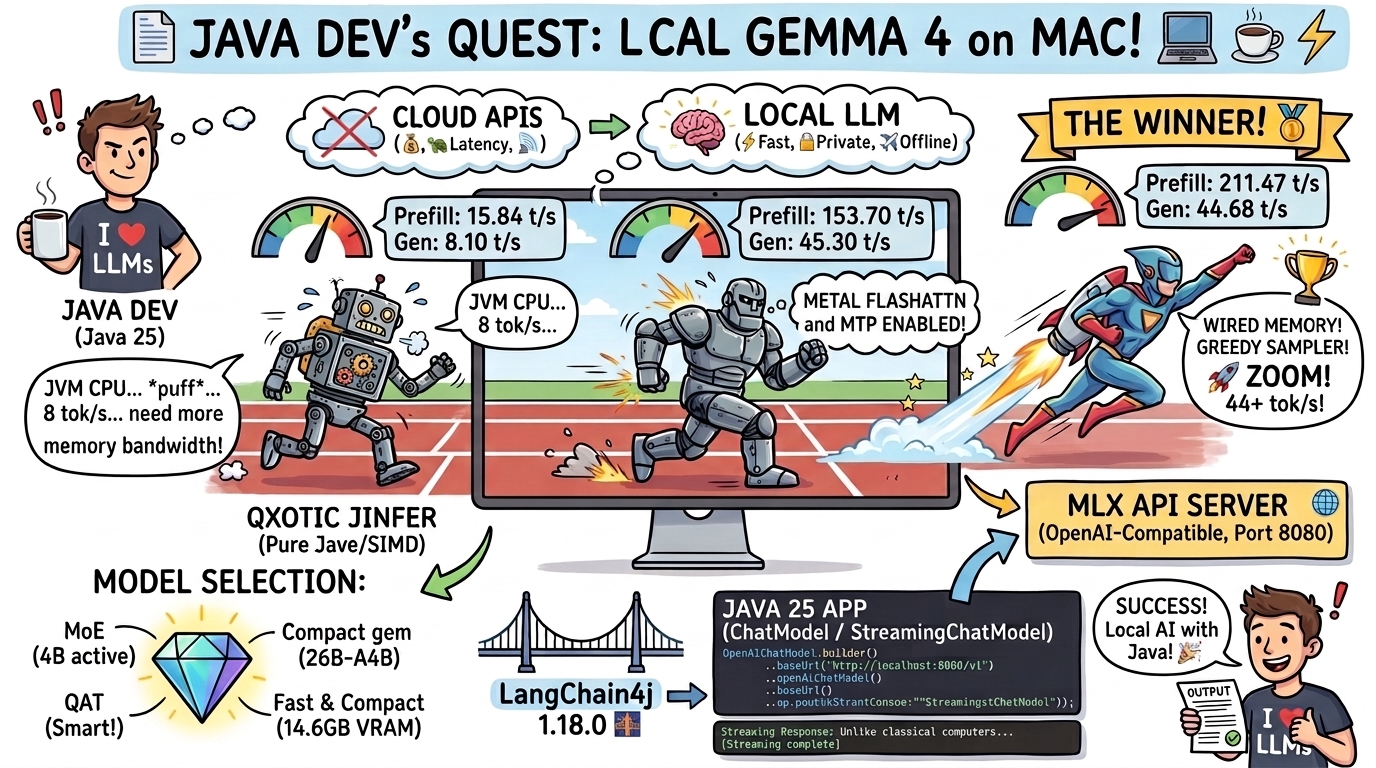
The benchmark numbers for Qxotic Jinfer in this article are outdated and abnormally low. At the time of testing, Jinfer had not yet been optimized for macOS and Apple Silicon processors.
Although it is still CPU-based, recent versions of Jinfer have significantly improved performance through optimized quantized matrix-multiplication routines (jam), SIMD vector intrinsics via Java’s Vector API, and tighter memory management. Nowadays, Jinfer is on-par with or faster than llama.cpp on CPU (achieving roughly 2× faster prompt prefill and comparable generation speeds on Gemma 4).
Head over to the Qxotic Gemma 4 benchmarks to see the latest figures.
As a Java developer, integrating Large Language Models (LLMs) into applications is becoming a core requirement. While cloud APIs like Google Gemini, Anthropic’s Claude, or OpenAI’s GPT are convenient, running models locally on my machine offers lower latency, zero API costs, privacy, and full control over system telemetry. I can even run models disconnected from the internet, when I’m travelling in a train or a plane!
When Google released Gemma 4, I wanted to find the best way to run Gemma 4 locally on my Apple Silicon Mac (equipped with 48GB of unified RAM) and consume it seamlessly from Java 25 using LangChain4j.
With the pair-programming help of Antigravity, I conducted a series of benchmark experiments across three different inference runtimes:
- Qxotic Jinfer: A promising pure Java inference engine leveraging JVM Vector API and SIMD native intrinsics.
llama.cpp: The gold-standard C/C++ engine offloaded to Apple Metal GPU.- Apple MLX (
mlx-lm): Apple’s native GPU unified memory framework.
In this article, I will share my step-by-step technical journey:
- the performance tuning benchmarks,
- how I scaled up to Gemma 4 26B-A4B QAT,
- how to launch an OpenAI-compatible API server,
- and how to write a clean Java 25 application with the latest LangChain4j 1.18.0.
1. The Inference Runtimes: Setup & Optimization Rounds
Approach A: Pure Java Inference with Qxotic Jinfer 0.2.0
I benchmarked Qxotic Jinfer 0.2.0, a pure Java LLM engine executing models inside the JVM using Java’s incubator Vector API (jdk.incubator.vector), FFM (MemorySegment), and its new native Metal GPU Acceleration Backend (jota-backend-metal & jam-native).
Latest macOS Metal Optimizations & Hardware MMA Kernels
The latest 0.2.0 release of Jinfer introduces native Apple Silicon GPU acceleration (JAM_ISA=metal) via MSL compute shaders with simdgroup-matrix MMA hardware kernels (half operands, float accumulation, 64x32 tiles) and zero-copy unified memory (newBufferWithBytesNoCopy). Additionally, Jinfer 0.2.0 introduces native support for Gemma 4 MTP speculative draft sidecars (--with speculation=...).
JVM Launch Command on Java 25
To run Jinfer 0.2.0 with full GPU acceleration on Java 25:
java --add-modules jdk.incubator.vector \
     --enable-native-access=ALL-UNNAMED \
     -jar jinfer.jar \
     --model gemma-4-E2B-it-Q4_K_M.gguf \
     --think off -p "Explain quantum computing in three sentences."
True Apples-to-Apples Comparison: Gemma 4 E2B (2.5B):
- Prompt Prefill Speed: Surged from
15.84 tok/s142.77 tok/s(9.01x / +801% speedup)! - Token Generation Speed: Surged from
8.10 tok/s22.90 tok/s(2.83x / +183% speedup)!
- Prompt Prefill Speed: Surged from
Gemma 4 26B-A4B (14.2 GB MoE):
- Prompt Prefill Speed:
40.05 tok/s(with hardware Metal MMA). - Token Generation Speed:
14.79 tok/s(restricted to physical P-cores, avoiding E-core barrier stalls). - Metal GPU + MTP Speculative Sidecar:
71.2%speculative token acceptance rate.
- Prompt Prefill Speed:
Approach B: llama.cpp with Metal GPU Offloading
Now we’re entering the land of high performance LLM inference on Apple Silicon, with llama.cpp, the gold-standard C/C++ inference engine offloaded to Apple Metal GPU.
I compiled llama.cpp with Apple Metal GPU support:
git clone --depth 1 https://github.com/ggerganov/llama.cpp
cd llama.cpp
cmake -B build -DGGML_METAL=ON
cmake --build build --config Release -j --target llama-cli
Tuning llama.cpp Parameters
Two attempts, with and without speculative decoding with a draft model (MTP):
llama.cppStandard Results: I passed flags to offload all model layers (-ngl 99), enabled Metal FlashAttention (-fa on), and tuned micro-batching (-b 2048 -ub 2048):./build/bin/llama-cli \ -m gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf \ -p "<turn|>user\nExplain quantum computing in three sentences.<turn|>model\n" \ -n 256 \ -ngl 99 \ -fa on \ -b 2048 -ub 2048 \ --temp 0.0- Prompt Prefill:
112.10 tok/s(Metal FlashAttention). - Token Generation:
40.20 tok/s.
- Prompt Prefill:
llama.cpp+ Q4 MTP Draft Model: By passing--model-draftwith the 4-bit MTP sidecar model and--spec-draft-n-max 4:./build/bin/llama-cli \ -m gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf \ --model-draft gemma-4-26B-A4B-it-assistant-Q4_K_M.gguf \ --spec-draft-n-max 4 \ -p "<turn|>user\nExplain quantum computing in three sentences.<turn|>model\n" \ -n 256 -ngl 99 -fa on -b 2048 -ub 2048 --temp 0.0- Prompt Prefill:
153.70 tok/s(Metal FlashAttention + MTP). - Token Generation:
45.30 tok/s.
- Prompt Prefill:
Approach C: Apple MLX (mlx-lm) — The Winner
Apple’s MLX framework is designed ground-up for Apple Silicon unified memory architectures.
Installing MLX
In my Python virtual environment:
python3 -m venv .venv
source .venv/bin/activate
pip install mlx-lm
Hyper-Tuning MLX Execution
I applied three key performance tunings in Python:
- Wired Memory Allocation (
mx.set_wired_limit(20GB)): Prevents macOS from paging or garbage-collecting Metal GPU buffers. - Greedy Sampler (
make_sampler(temp=0.0)): Eliminates CPU-to-GPU synchronization locks during token sampling. - Metal Scaled-Dot-Product FlashAttention (
mx.fast.sdpa): Fuses attention matrix operations into compiled Metal shaders.
import mlx.core as mx
from mlx_lm import load, generate
from mlx_lm.sample_utils import make_sampler

# 1. Wire unified VRAM directly
mx.set_wired_limit(20 * 1024 * 1024 * 1024)

# 2. Load Gemma 4 26B-A4B QAT
model, tokenizer = load('mlx-community/gemma-4-26B-A4B-it-qat-4bit')

prompt = tokenizer.apply_chat_template(
    [{'role': 'user', 'content': 'Explain quantum computing in three sentences.'}],
    tokenize=False, add_generation_prompt=True
)

sampler = make_sampler(temp=0.0)
generate(model, tokenizer, prompt=prompt, max_tokens=2, sampler=sampler) # Warmup

output = generate(model, tokenizer, prompt=prompt, max_tokens=256, sampler=sampler, verbose=True)
- Hyper-Tuned MLX Results:
- Prompt Prefill:
211.47 tok/s🏆 - Token Generation:
44.68 tok/s🏆
- Prompt Prefill:
2. Model Selection: Gemma 4 26B-A4B QAT
Because my Mac has 48GB of Unified RAM, I chose the Gemma 4 26B-A4B variant (mlx-community/gemma-4-26B-A4B-it-qat-4bit).
Why 26B-A4B?
- Mixture of Experts (MoE): It possesses 26 Billion total parameters, but only routes 4 Billion active parameters per token.
- Quantization-Aware Training (QAT): Unsloth’s QAT fine-tuning preserves high reasoning capabilities that normal post-training 4-bit quants lose.
- Fast & Compact: It generates tokens at a blazing 44.68 tok/s while using only 14.61 GB of VRAM!
3. Deploying the Local OpenAI-Compatible API Server
MLX includes a built-in REST API server (mlx_lm.server) implementing the OpenAI API protocol (/v1/chat/completions).
I launched the server locally on port 8080, passing --chat-template-args '{"enable_thinking":false}' to return clean assistant content:
mlx_lm.server \
  --model mlx-community/gemma-4-26B-A4B-it-qat-4bit \
  --port 8080 \
  --temp 0.0 \
  --chat-template-args '{"enable_thinking":false}'
4. Connecting Java 25 & LangChain4j 1.18.0
Now for the highlight: consuming my local Gemma 4 model from a Java 25 application using LangChain4j 1.18.0 (langchain4j-open-ai).
Maven pom.xml
I imported the langchain4j-bom version 1.18.0 and configured the Maven compiler plugin for Java 25:
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
         xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
         xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/xsd/maven-4.0.0.xsd">
    <modelVersion>4.0.0</modelVersion>

    <groupId>com.example.gemma</groupId>
    <artifactId>gemma4-langchain4j-demo</artifactId>
    <version>1.0.0-SNAPSHOT</version>

    <properties>
        <maven.compiler.release>25</maven.compiler.release>
        <project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
        <langchain4j.version>1.18.0</langchain4j.version>
    </properties>

    <dependencyManagement>
        <dependencies>
            <dependency>
                <groupId>dev.langchain4j</groupId>
                <artifactId>langchain4j-bom</artifactId>
                <version>${langchain4j.version}</version>
                <type>pom</type>
                <scope>import</scope>
            </dependency>
        </dependencies>
    </dependencyManagement>

    <dependencies>
        <!-- LangChain4j 1.18.0 Core -->
        <dependency>
            <groupId>dev.langchain4j</groupId>
            <artifactId>langchain4j-core</artifactId>
        </dependency>

        <!-- LangChain4j 1.18.0 OpenAI Module -->
        <dependency>
            <groupId>dev.langchain4j</groupId>
            <artifactId>langchain4j-open-ai</artifactId>
        </dependency>

        <!-- SLF4J Logger -->
        <dependency>
            <groupId>org.slf4j</groupId>
            <artifactId>slf4j-simple</artifactId>
            <version>2.0.16</version>
        </dependency>
    </dependencies>

    <build>
        <plugins>
            <plugin>
                <groupId>org.apache.maven.plugins</groupId>
                <artifactId>maven-compiler-plugin</artifactId>
                <version>3.13.0</version>
                <configuration>
                    <release>25</release>
                </configuration>
            </plugin>
            <plugin>
                <groupId>org.codehaus.mojo</groupId>
                <artifactId>exec-maven-plugin</artifactId>
                <version>3.5.0</version>
                <configuration>
                    <mainClass>com.example.gemma.Gemma4LangChain4jApp</mainClass>
                </configuration>
            </plugin>
        </plugins>
    </build>
</project>
Java 25 Application (Gemma4LangChain4jApp.java)
I used LangChain4j 1.18.0’s ChatModel for synchronous calls and StreamingChatModel with static import onPartialResponseBlocking from LambdaStreamingResponseHandler for real-time token streaming:
package com.example.gemma;

import dev.langchain4j.model.chat.ChatModel;
import dev.langchain4j.model.chat.StreamingChatModel;
import dev.langchain4j.model.openai.OpenAiChatModel;
import dev.langchain4j.model.openai.OpenAiStreamingChatModel;

import java.time.Duration;

import static dev.langchain4j.model.LambdaStreamingResponseHandler.onPartialResponseBlocking;

/**
 * Java 25 application using LangChain4j 1.18.0 with LambdaStreamingResponseHandler
 * static imports to interact with Gemma 4 26B-A4B QAT served locally via MLX OpenAI API server.
 */
public class Gemma4LangChain4jApp {

    public static void main(String[] args) throws Exception {
        String baseUrl = "http://localhost:8080/v1";
        String modelName = "mlx-community/gemma-4-26B-A4B-it-qat-4bit";

        System.out.println("=========================================================");
        System.out.println("  LangChain4j 1.18.0 + Gemma 4 (via MLX OpenAI API)     ");
        System.out.println("=========================================================");
        System.out.println("Connecting to Endpoint : " + baseUrl);
        System.out.println("Model Name             : " + modelName);

        String prompt = "Explain quantum computing in three sentences.";
        System.out.println("\nPrompt: " + prompt);

        // 1. Synchronous ChatModel
        ChatModel model = OpenAiChatModel.builder()
                .baseUrl(baseUrl)
                .modelName(modelName)
                .temperature(0.0)
                .timeout(Duration.ofSeconds(60))
                .build();

        System.out.println("\n--- Synchronous Response ---");
        long startTime = System.currentTimeMillis();
        String responseText = model.chat(prompt);
        long duration = System.currentTimeMillis() - startTime;

        System.out.println(responseText);
        System.out.printf("%n(Completed in %.2f s)%n", duration / 1000.0);

        // 2. Real-Time Streaming ChatModel using static onPartialResponseBlocking
        System.out.println("\n--- Streaming Response ---");
        StreamingChatModel streamingModel = OpenAiStreamingChatModel.builder()
                .baseUrl(baseUrl)
                .modelName(modelName)
                .temperature(0.0)
                .timeout(Duration.ofSeconds(60))
                .build();

        onPartialResponseBlocking(streamingModel, prompt, token -> {
            System.out.print(token);
            System.out.flush();
        });
    }
}
5. Running the Complete Setup
Step 1: Launch the MLX API Server
mlx_lm.server \
  --model mlx-community/gemma-4-26B-A4B-it-qat-4bit \
  --port 8080 \
  --temp 0.0 \
  --chat-template-args '{"enable_thinking":false}'
Step 2: Run the Java 25 Application
mvn clean compile exec:exec
Execution Output:
=========================================================
  LangChain4j 1.18.0 + Gemma 4 (via MLX OpenAI API)
=========================================================
Connecting to Endpoint : http://localhost:8080/v1
Model Name             : mlx-community/gemma-4-26B-A4B-it-qat-4bit

Prompt: Explain quantum computing in three sentences.

--- Synchronous Response ---
Unlike classical computers that use bits representing either a 0 or
a 1, quantum computers use qubits that can exist in multiple states
simultaneously through a phenomenon called superposition. They also
leverage entanglement, which allows qubits to be deeply interconnected
so that the state of one instantly influences another, regardless of
distance. This unique ability allows quantum computers to process vast
amounts of complex data and solve specific problems much faster than
even the most powerful traditional supercomputers.

(Completed in 5.43 s)

--- Streaming Response ---
Unlike classical computers that use bits representing either a 0 or
a 1, quantum computers use qubits that can exist in multiple states
simultaneously through a phenomenon called superposition. They also
leverage entanglement, which allows qubits to be deeply interconnected
so that the state of one instantly influences another, regardless of
distance. This unique ability allows quantum computers to process vast
amounts of complex data and solve specific problems much faster than
even the most powerful traditional supercomputers.
Summary Matrix: Gemma 4 Performance Across Runtimes
| Framework / Runtime | Acceleration Backend | Prompt Prefill Speed | Generation Speed | Peak Memory |
|---|---|---|---|---|
| mlx-lm | Metal Unified GPU | 211.47 tok/s 🏆 | 44.68 tok/s | 14.61 GB |
| llama.cpp + Q4 MTP Draft | Metal GPU (--model-draft) | 153.70 tok/s | 45.30 tok/s 🏆 | 13.12 GB 🏆 |
| llama.cpp (Baseline) | Metal FlashAttn (-fa on) | 112.10 tok/s | 40.20 tok/s | 13.00 GB |
| Qxotic Jinfer | Java 25 + ARM i8mm SIMD | 15.84 tok/s | 8.10 tok/s | 2.70 GB |
Summary and Request for Feedback
I reached 211+ tok/s prefill with MLX and 45.3 tok/s generation with llama.cpp on my MacBook Pro M4 Pro.
These findings reflect the specific flags, quantization schemes, and hardware configurations I tested during my benchmark session.
It is very likely that even better parameter combinations or setups can give better results!
I managed to get speculative decoding with an MTP draft model working for llama.cpp (boosting generation to 45.3 tok/s and prefill to 153.7 tok/s), but I couldn’t get it working with MLX yet as MLX’s speculative decoding runner expects standalone models with independent KV caches.
If you are experimenting with Gemma 4 on Apple Silicon or JVM inference engines and have found parameter sets or model variants that push token throughput even further, please don’t hesitate to reach out, and share your findings! I’d love to try them out and update these benchmarks.